
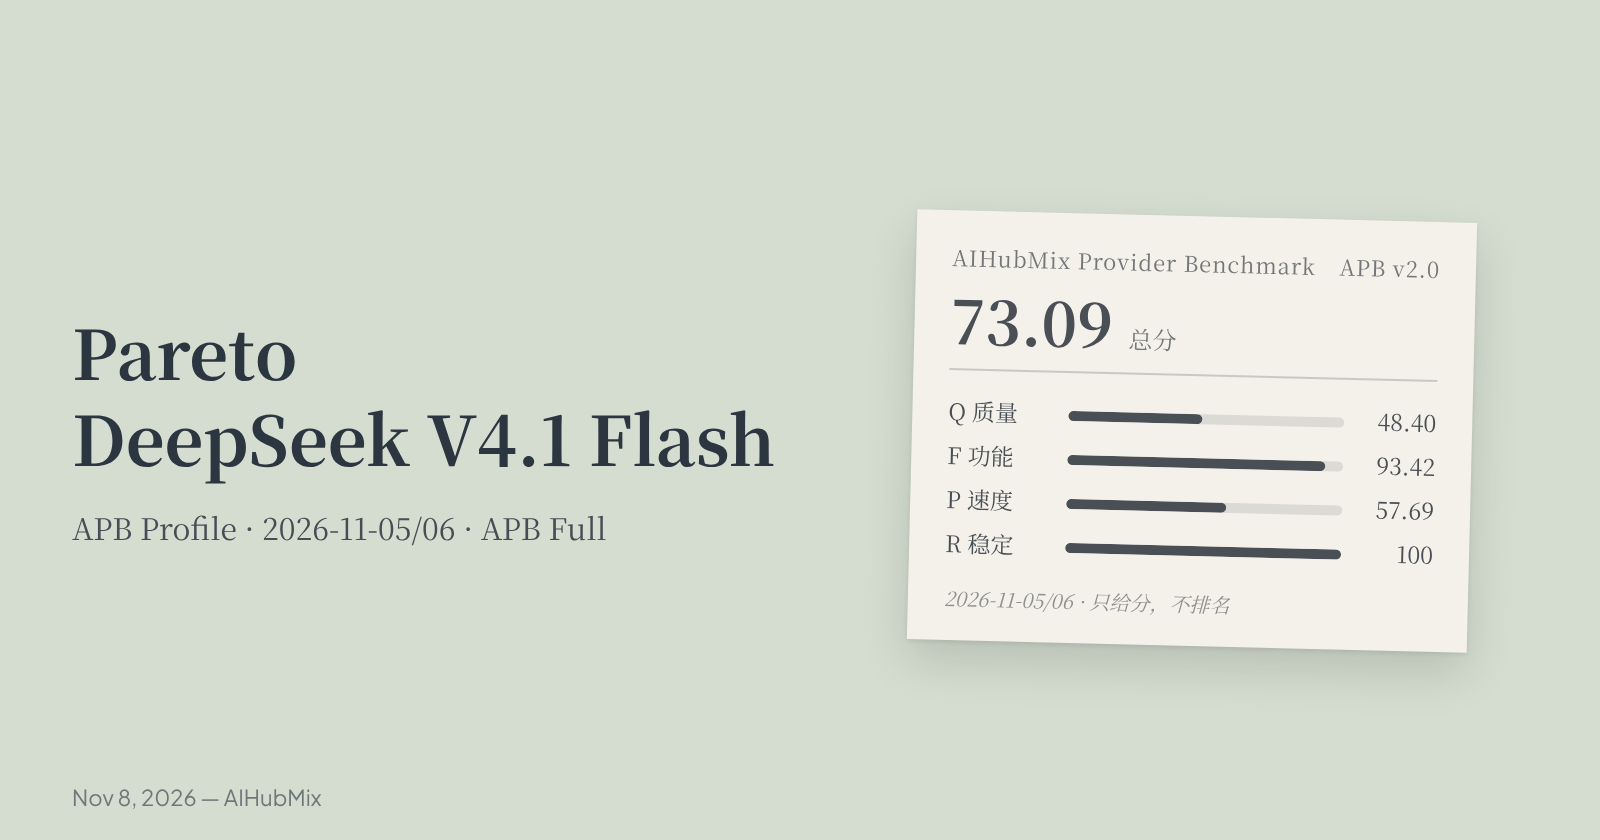
On 2026-11-05/06, DeepSeek V4.1 Flash 1017 was run through the AIHubMix Provider Benchmark (APB) Full suite on Pareto. Scores are Q 48.40, F 93.42, P 57.69, K 27.58 and R 100; the overall index is 73.09. This APB Profile covers Pareto only. The model is listed as DeepSeek V4.1 Flash 1017.
This post reports scores only, with no ranking or provider recommendation. Q, F, P, K and R come first; the overall index is a summary number with no confidence interval. The standard is AIHubMix Provider Benchmark Standard v2.0.
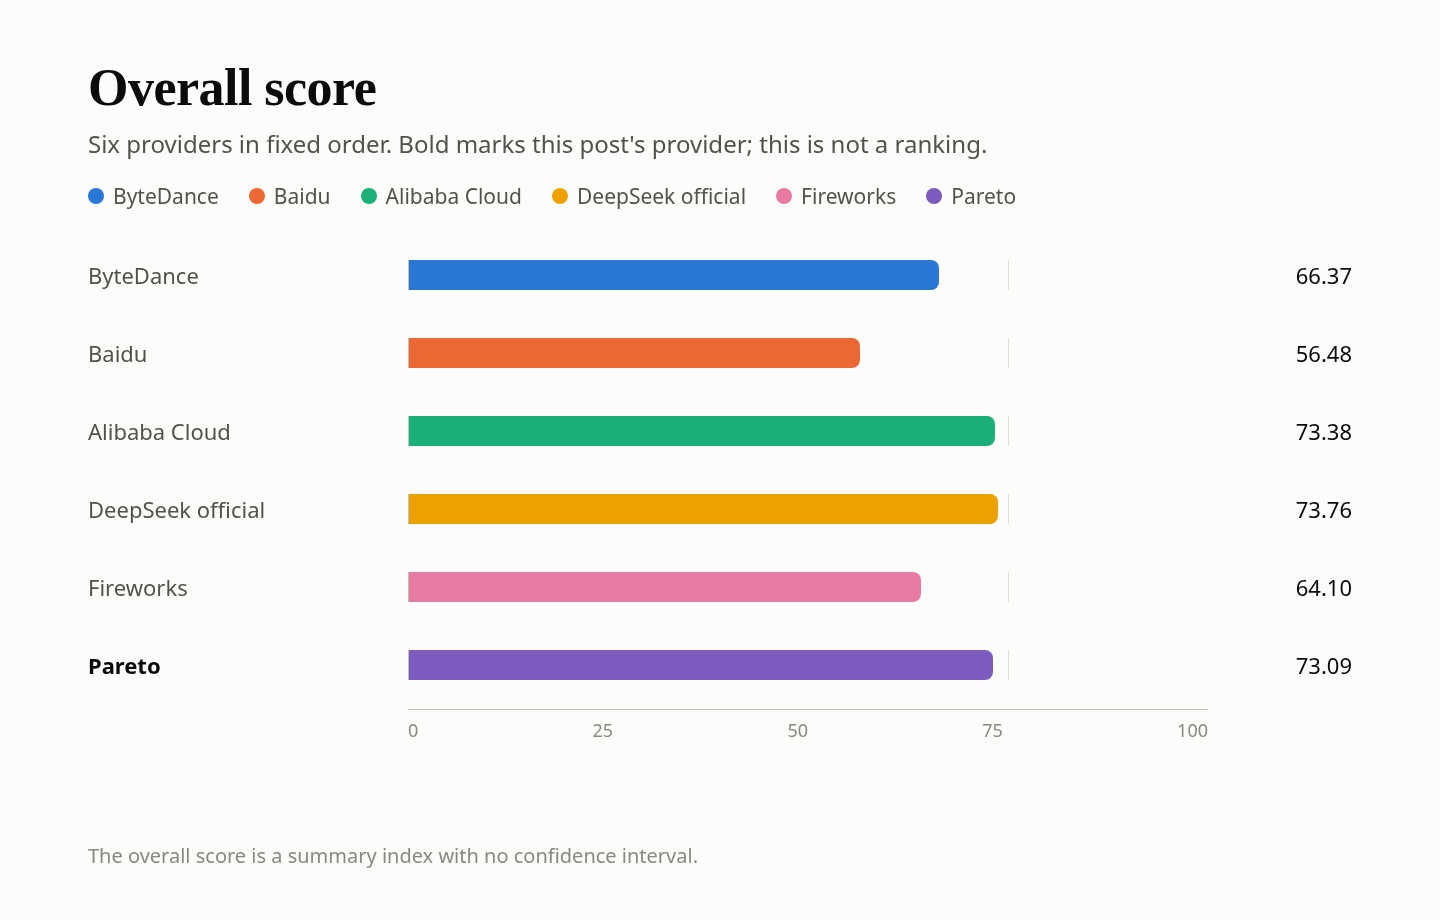
Scores across six providers
Bold marks this post's provider. Fixed provider order, not a ranking. K is a sub-score of P at 20%. The overall index is a summary number with no confidence interval. DeepSeek official channel and Alibaba Cloud differ by 0.37 and are not distinguishable.
At a glance
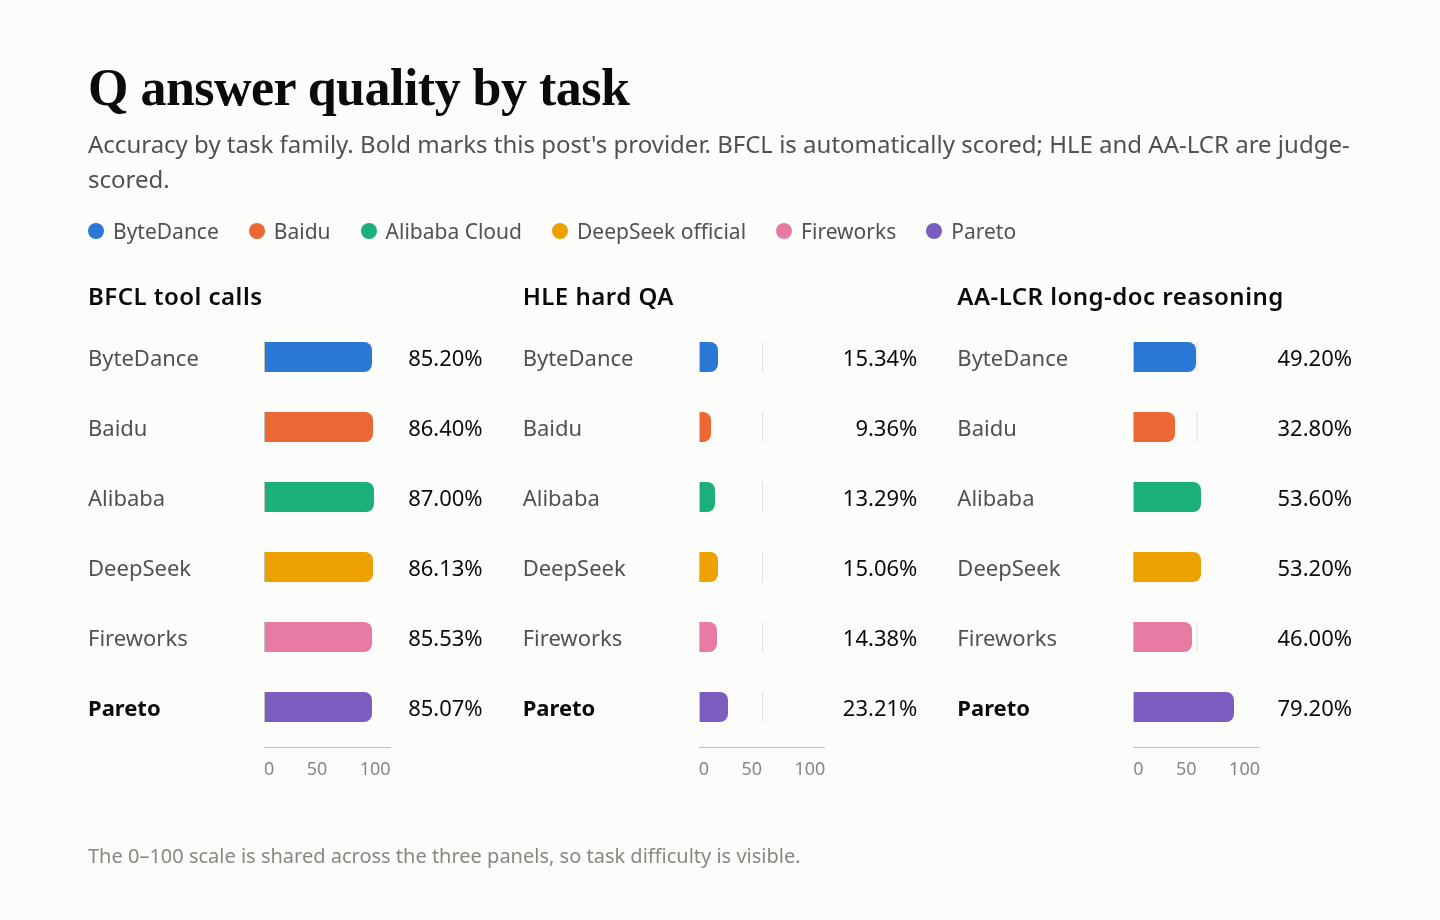
- Q — answer quality: 48.40. BFCL 85.07%, HLE 23.21%, AA-LCR 79.20%. Against the official channel: +5.94 percentage points, 95% CI +3.54 to +8.36. HLE had 996 service failures, most truncated because thinking consumed the output-length budget; they count as incorrect.
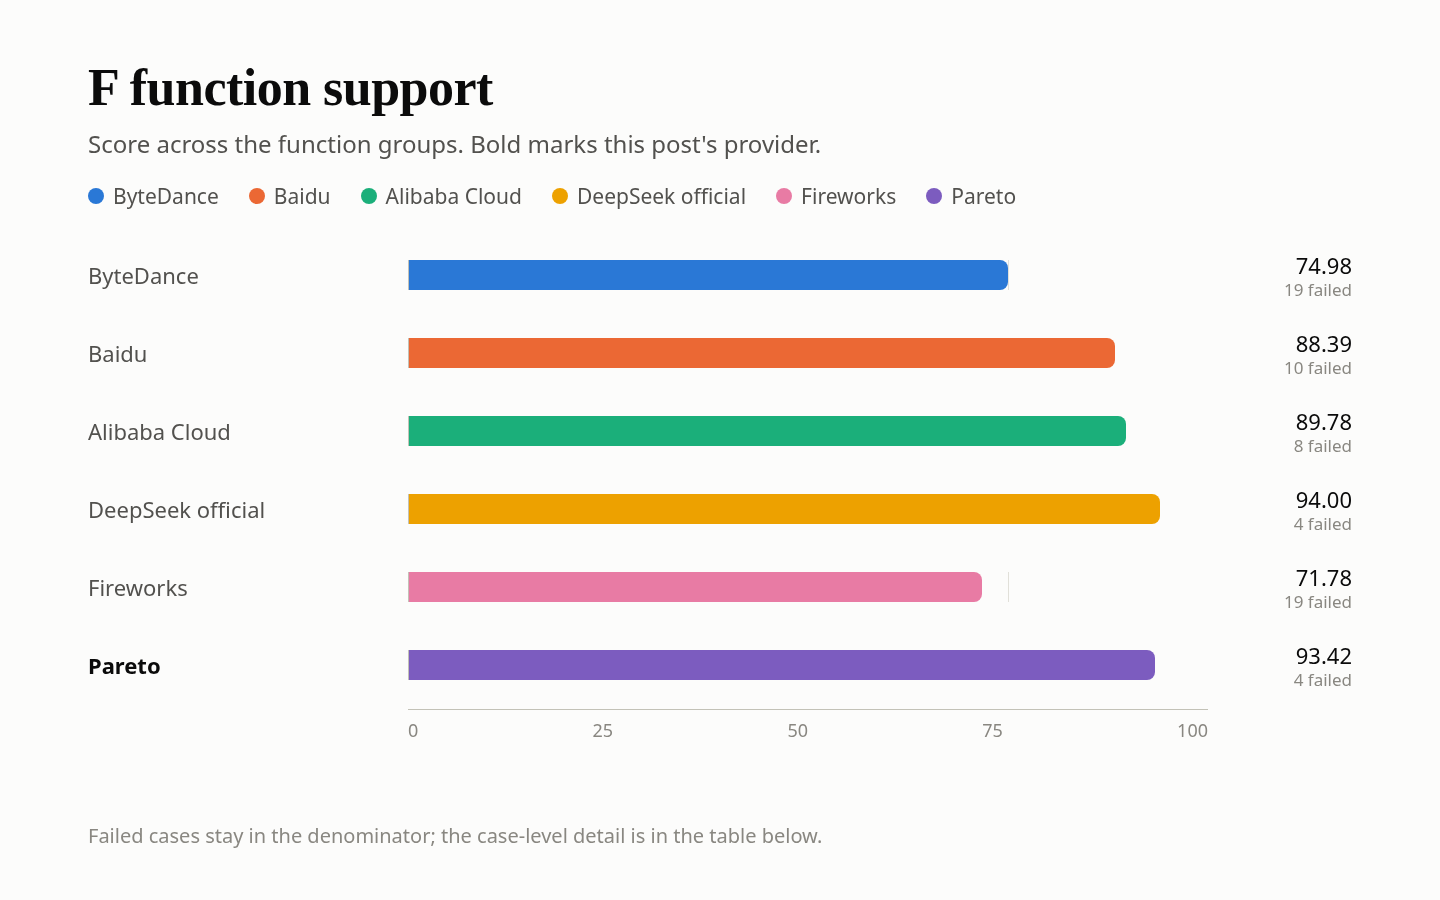
- F — function support: 93.42. 29 of 33 counted checks passed (streaming 23/27, errors 3/3, metering 3/3). 147 checks were out of denominator. Of 4 failures, 3 were empty bodies on stop-sequence requests, and 1 streaming text fixture did not match exactly.
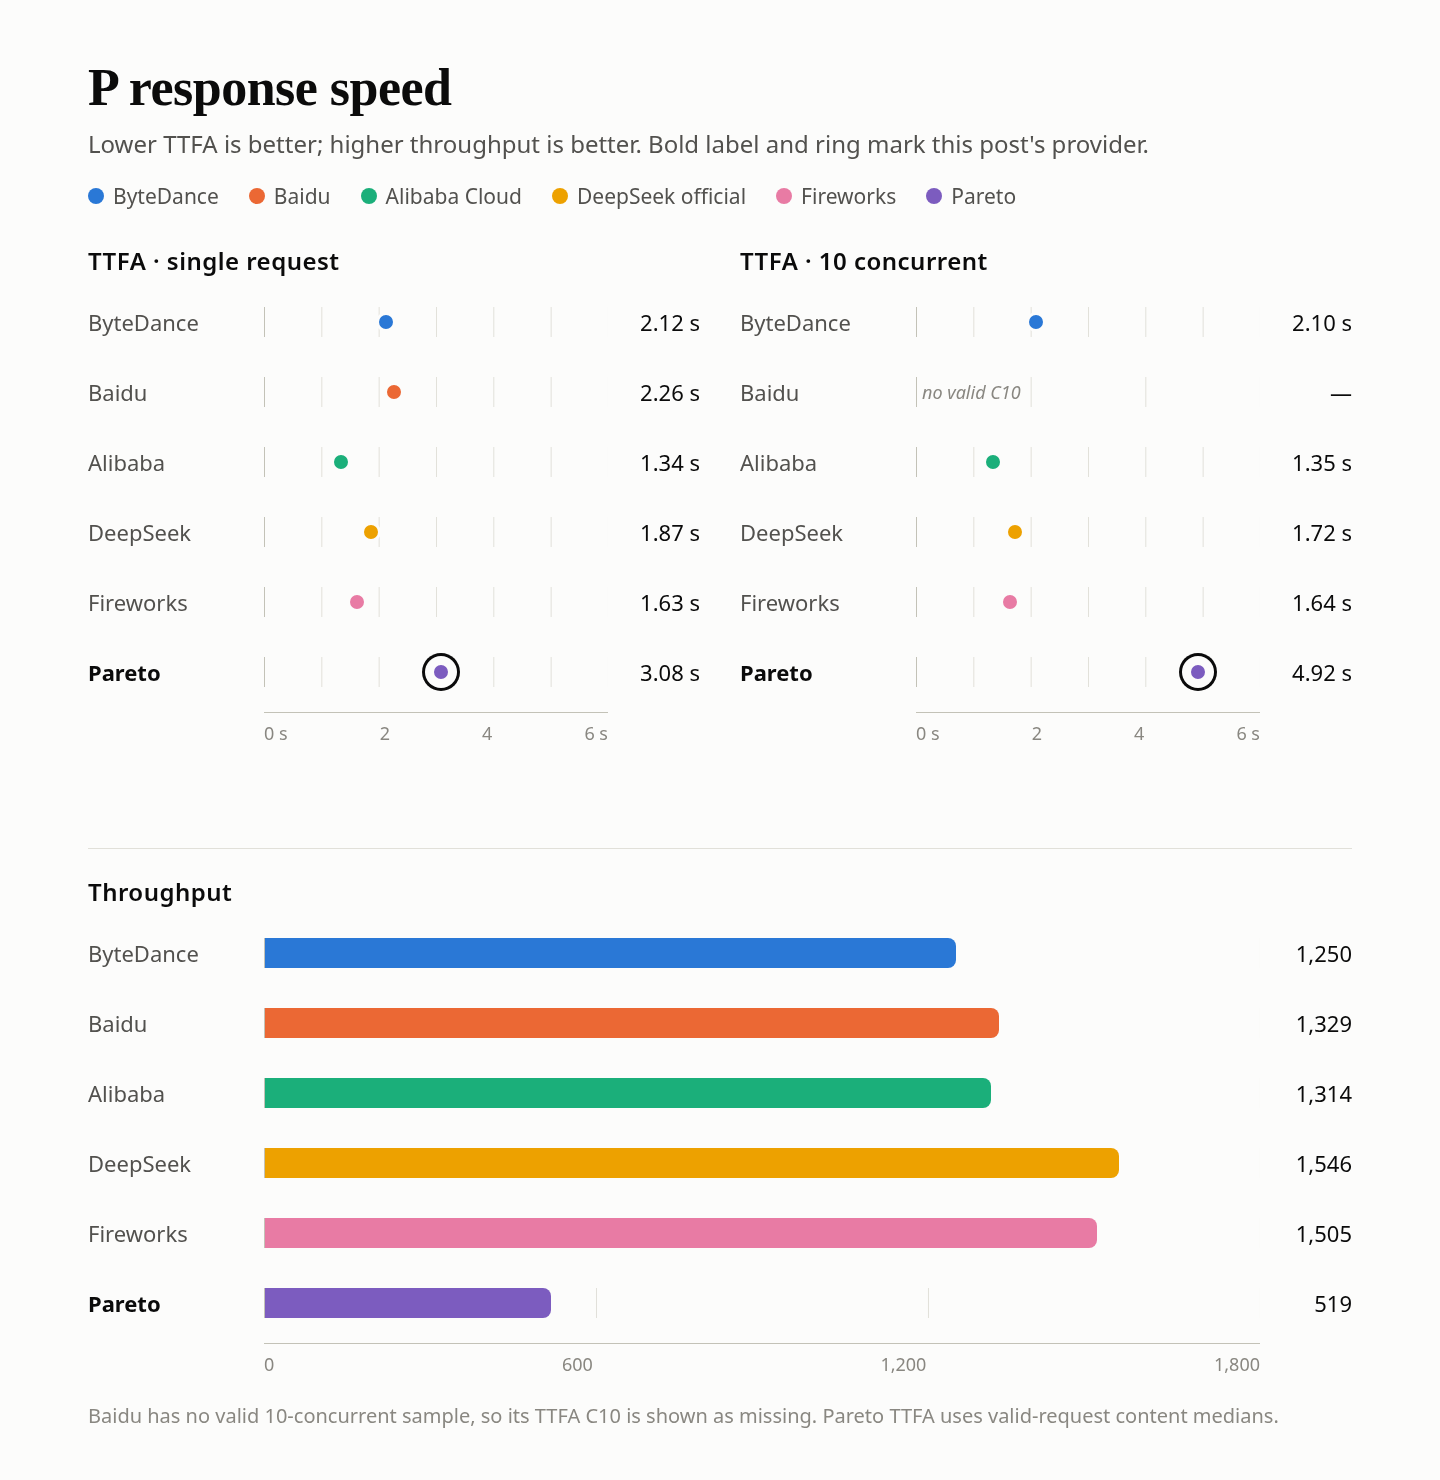
- P — response speed: 57.69. Response score 65.22, cache K at 20%. Valid-request TTFA medians 3.08 s single and 4.92 s at 10 concurrent; scoring medians including invalid requests 5.85 s and 6.13 s. 110 of 180 probes were valid; 70 invalid because thinking consumed the speed-test output budget.
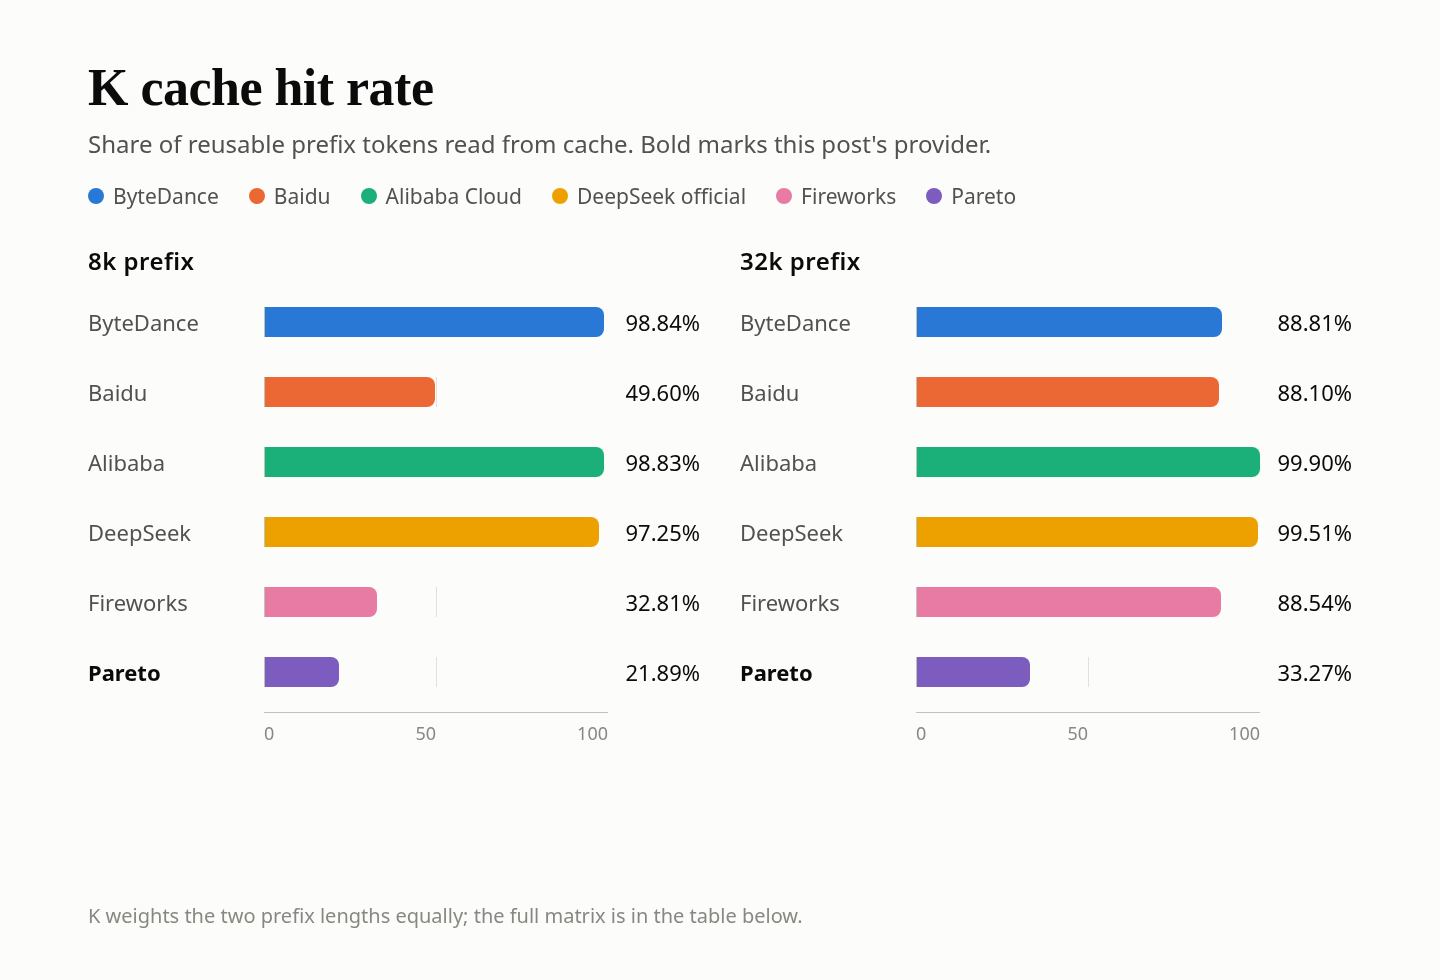
- K — cache: 27.58. 8k hot 2/9 (read 15,872 / reusable 72,504); 32k hot 3/9 (read 96,000 / reusable 288,513). Scored under the default configuration.
- R — service stability: 100. 300/300 dedicated requests succeeded on the first attempt.
Test setup
| Item | Setting |
|---|---|
| Model | DeepSeek V4.1 Flash 1017 |
| Requested model ID | deepseek/deepseek-v4.1-flash |
| Access route | Pareto, using the model ID above |
| Parameters | temperature 1.0, max_tokens 16,384, timeout 300 s; streaming requests only |
| Thinking | High-intensity thinking enabled |
| Time | 2026-11-05/06 UTC+8; cache is a 2026-11-06 default-configuration retest |
| Samples | Q 4,250 (BFCL 500×3, HLE 250×10, AA-LCR 25×10); F 60×3; P 90+90; R 300; K 30 |
| Notes | Thinking high-intensity on this run; the other five providers in the series used none. Feature support is scored on the streaming-available subset; cache uses the default configuration. |
Requests used the AIHubMix quick start; model IDs are on the models page.
Q — answer quality: 48.40
The suite ran 500 BFCL questions × 3 rounds, 250 HLE × 10 and 25 AA-LCR × 10. BFCL was auto-scored; HLE and AA-LCR were judged by deepseek-flash. The three families use the same items as the other providers. Ten unscoreable answers were removed, leaving 4,240 scored instances.
| Task | Questions | Correct | Accuracy | Failures |
|---|---|---|---|---|
| BFCL tool calls | 500 × 3 | 1,276/1,500 | 85.07% | 0 |
| HLE hard QA | 250 × 10 | 578/2,490 | 23.21% | 996 |
| AA-LCR long-doc reasoning | 25 × 10 | 198/250 | 79.20% | 0 |
| Total · 95% CI 45.39%–51.26% | — | 2,052/4,240 | 48.40% | 996 |
Failures stay in the denominator as wrong: HLE 996 truncated when thinking consumed the output-length budget. Among the 1,494 HLE attempts that returned a complete answer, 578 were correct (about 38.7%).
| BFCL category | Passed | Pass rate |
|---|---|---|
| simple_python | 333/360 | 92.50% |
| multiple | 269/300 | 89.67% |
| parallel | 265/300 | 88.33% |
| parallel_multiple | 203/240 | 84.58% |
| irrelevance | 104/150 | 69.33% |
| ahm_multi_turn | 102/150 | 68.00% |
simple_python passed 333/360 (92.50%), multiple 269/300 (89.67%), ahm_multi_turn 102/150 (68.00%) and irrelevance 104/150 (69.33%).
Compared with the other five
Difference in percentage points against the official channel; 95% interval shown as whiskers. Crossing 0 means not distinguishable. The deepseek-flash judge is in the same family and uncalibrated, so may be lenient.
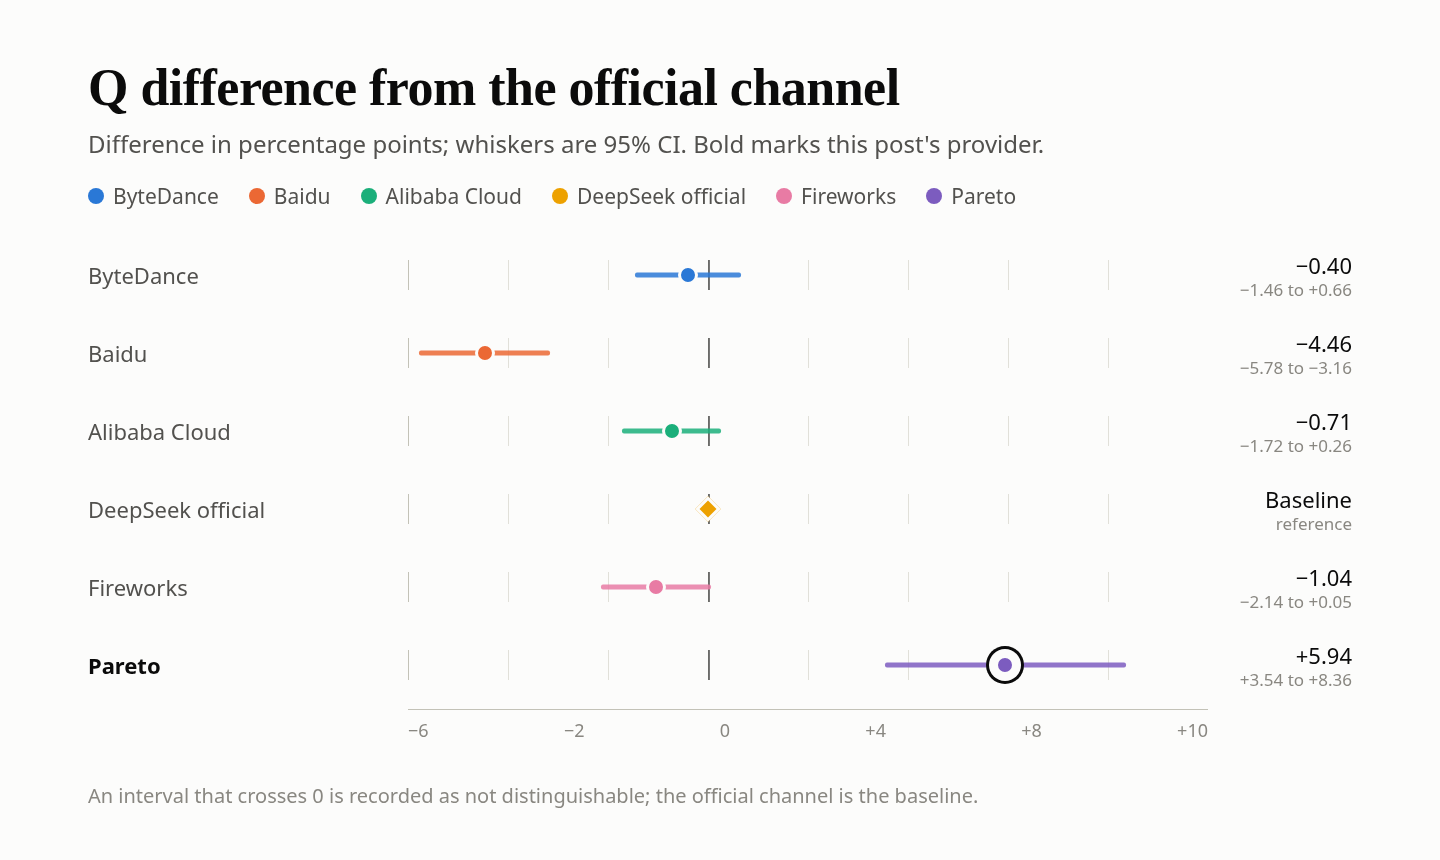
Versus the official channel, the numeric difference is +5.94 (+3.54 to +8.36).
F — function support: 93.42
33 counted checks, 29 passed; 147 not counted. The 93.42 figure renormalizes the original group weights over the observed groups (streaming 20%, errors 15%, metering 10%; total 45%). The simple pass rate 29/33 is 87.88%. Tools, constraints and context were entirely uncounted.
| Case group | Weight | Passed | Excluded | Group score |
|---|---|---|---|---|
| Streaming and messaging | 20% | 23/27 | 3 | 85.19 |
| Tool interface | 20% | — | 30 | — |
| Output constraints | 20% | — | 30 | — |
| Context and state | 15% | — | 30 | — |
| Error and recovery | 15% | 3/3 | 27 | 100.00 |
| Metering and cache | 10% | 3/3 | 27 | 100.00 |
| Observed / weighted | — | 29/33 | 147 | 93.42 |
"Windows failed" counts the three windows in which the case did not pass.
| Failed case | Windows failed | Reason |
|---|---|---|
| Streaming stop | 3/3 | Empty body with stop |
| Streaming text | 1/3 | Extra period at end of body vs fixture |
Compared with the other five
P — response speed: 57.69
Scoring uses time-to-first-content-token, not time-to-first-any-token. With thinking enabled, the model writes thinking content before visible answer text, so content wait is longer than first-packet wait. In each of three windows, 30 requests were sent at single concurrency and 30 at 10 concurrency, for 180 in total.
| Metric | Result |
|---|---|
| Content TTFA | Scoring medians 5.85 s (c=1) and 6.13 s (c=10); valid-request medians 3.08 s and 4.92 s |
| First any token | Valid-request medians 1.46 s and 1.76 s |
| TPOT | Slower scoring band 4.87 ms/token |
| Goodput | 519 token/s at concurrency 10 |
| Valid | 53/90 at c=1 and 57/90 at c=10, total 110/180; 70 invalid because thinking consumed the speed-test output budget (~2,048 tokens) |
| Components | TTFA 24.59, TPOT 100.00, goodput 72.05; response score 65.22 |
| P composition | 65.22 × 80% + 27.58 × 20% = 57.69 |
Thinking tokens are excluded from the goodput numerator.
K — cache: 27.58
Aggregate reads from the 2026-11-06 default-configuration retest. Per-request cache matrices are not included (raw traces were not migrated). K weights the two prefix lengths equally; K is 20% of P.
| Prefix | Hot hits | Read / reusable | Segment |
|---|---|---|---|
| 8k | 2/9 | 15,872 / 72,504 | 21.89 |
| 32k | 3/9 | 96,000 / 288,513 | 33.27 |
| K (equal weight) | 27.58 |
Cold controls passed 6/6 at each length.
R — service stability: 100
300 requests covered short text, long input, tool calling and multi-turn history at single concurrency. Only first-response validity and completeness were checked; answers were not graded and nothing was retried. Q and P failures are not recounted here.
| Request type | First-attempt success |
|---|---|
| Short text | 120/120 |
| 10k long input | 90/90 |
| Tool calling | 60/60 |
| Multi-turn history | 30/30 |
| Total · 95% CI 98.78%–100% | 300/300 |
FAQ
What does Q 48.40 cover?
BFCL, HLE and AA-LCR over 4,240 scored instances: 2,052 correct, 48.40%, 95% CI 45.39%–51.26%. Versus the official channel the numeric difference is +5.94 (+3.54 to +8.36).
Why were there 996 HLE service failures?
Most were truncated because thinking consumed the output-length budget; they stay in the denominator as incorrect.
Why is F 93.42 with 147 checks excluded?
Only the streaming-available subset is counted. Group weights are renormalized over the observed groups; tools, constraints and context are entirely uncounted.
Why did stop cases fail?
Requests with a stop sequence returned an empty body in all three windows.
Why were 70 of 180 speed probes invalid?
Thinking consumed the speed-test output budget (about 2,048 tokens).
What does R 100 cover?
300 dedicated requests, all valid on the first attempt; the 95% lower bound is 98.78%. Q and P failures are not counted in R.
Keep reading: the DeepSeek V4.1 Flash series
- ByteDance reported thinking tokens after thinking was disabled: DeepSeek V4.1 Flash on ByteDance: tool calls match, metering doesn't
- Baidu recorded Q 38.00 and P 37.77: DeepSeek V4.1 Flash on Baidu: no available channel hits Q and P
- Alibaba Cloud recorded a 1.34 s first token and 99.37 cache: DeepSeek V4.1 Flash on Alibaba Cloud: 1.34s first token, 99.37 cache
- The official channel is the Q baseline, with F 94.00: DeepSeek V4.1 Flash on the official channel: 94.00 F, 15 invalid probes
- Fireworks returned empty stop replies and 3/9 cache hits at 8k: DeepSeek V4.1 Flash on Fireworks: empty stop replies, 3/9 cache hits


