
On 2026-11-03/04, DeepSeek V4.1 Flash 1017 was tested on five providers through AIHubMix with the APB Full suite: the same questions, parameters and request scripts each time. This APB Profile covers the ByteDance run only, section by section.
The numbers below are scores, not a ranking or a provider recommendation. Q, F, P, K and R come first; the overall is a summary index, not a certification, and it has no confidence interval. The scoring rules are defined in AIHubMix Provider Benchmark Standard v2.0.
Scores across five providers
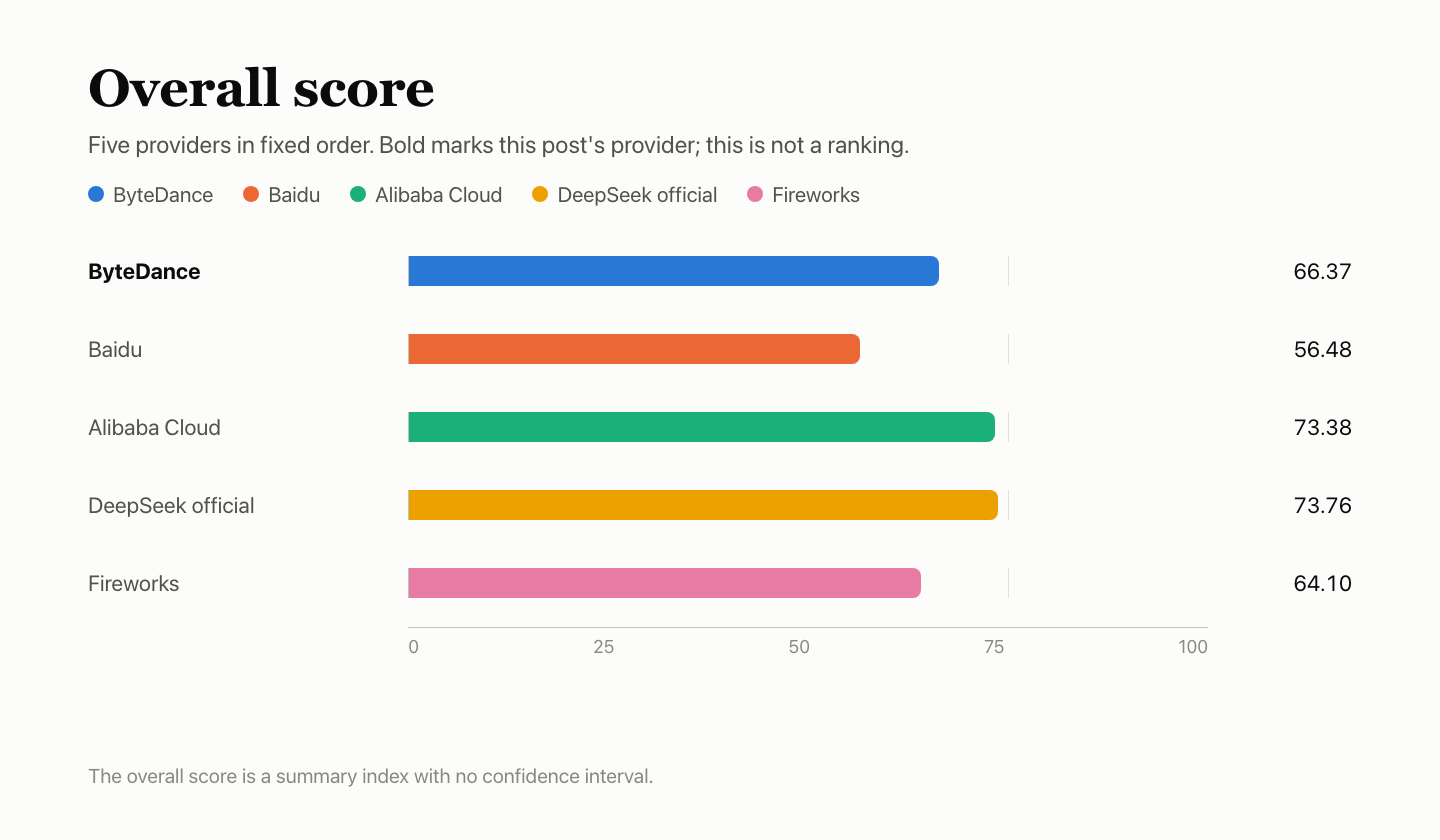
Bold marks this post's provider. Fixed provider order, not a ranking. K is a sub-score of P and accounts for 20% of it. The overall is a summary index with no confidence interval. DeepSeek official channel and Alibaba Cloud differ by 0.37 and are not distinguishable.
At a glance
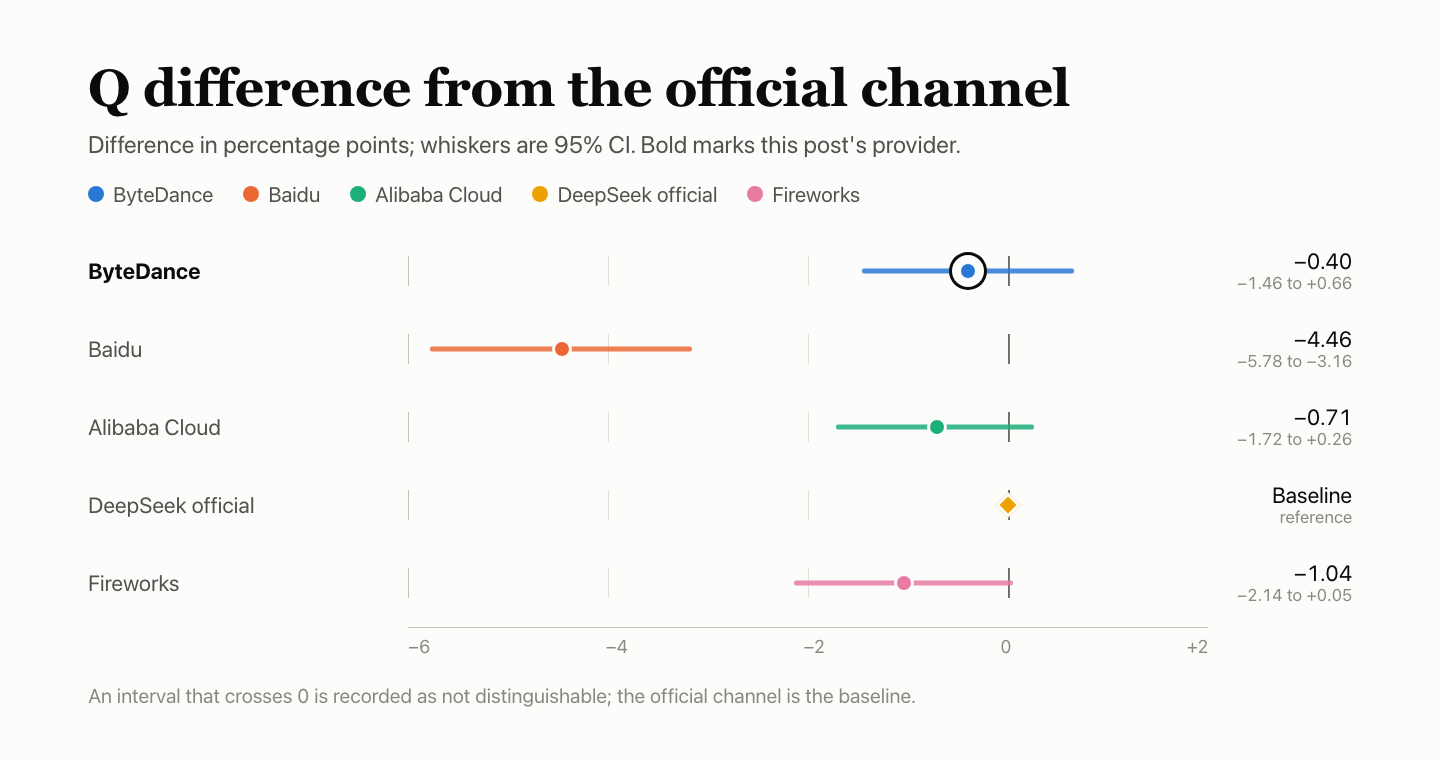
- Q 42.05. BFCL 85.20%, HLE 15.34%, AA-LCR 49.20%. The gap to the official channel is −0.40 percentage points, with a 95% interval of −1.46 to +0.66: not distinguishable. AA-LCR had 28 request failures, all in window 1, counted as wrong.
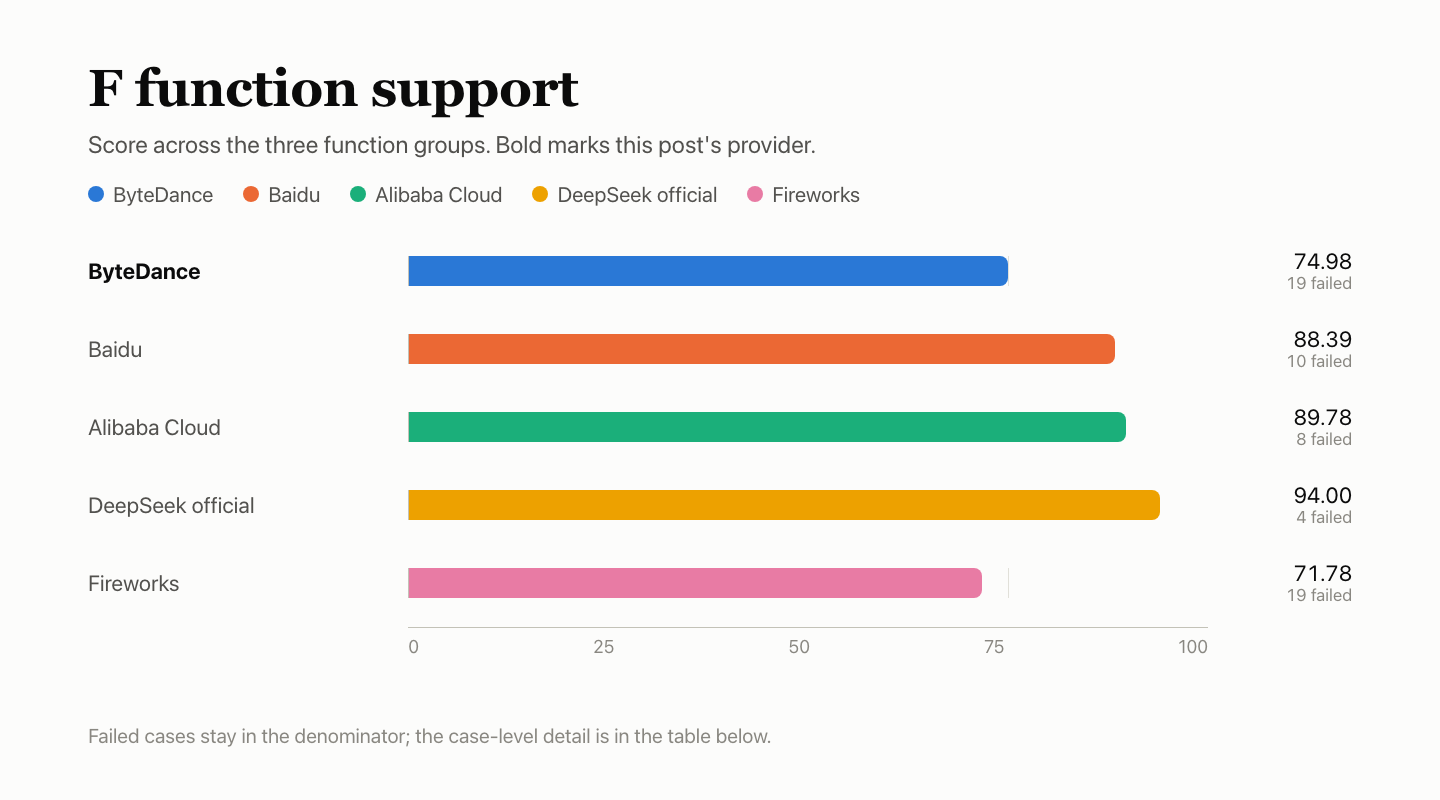
- F 74.98. 124 of 174 counted checks passed.
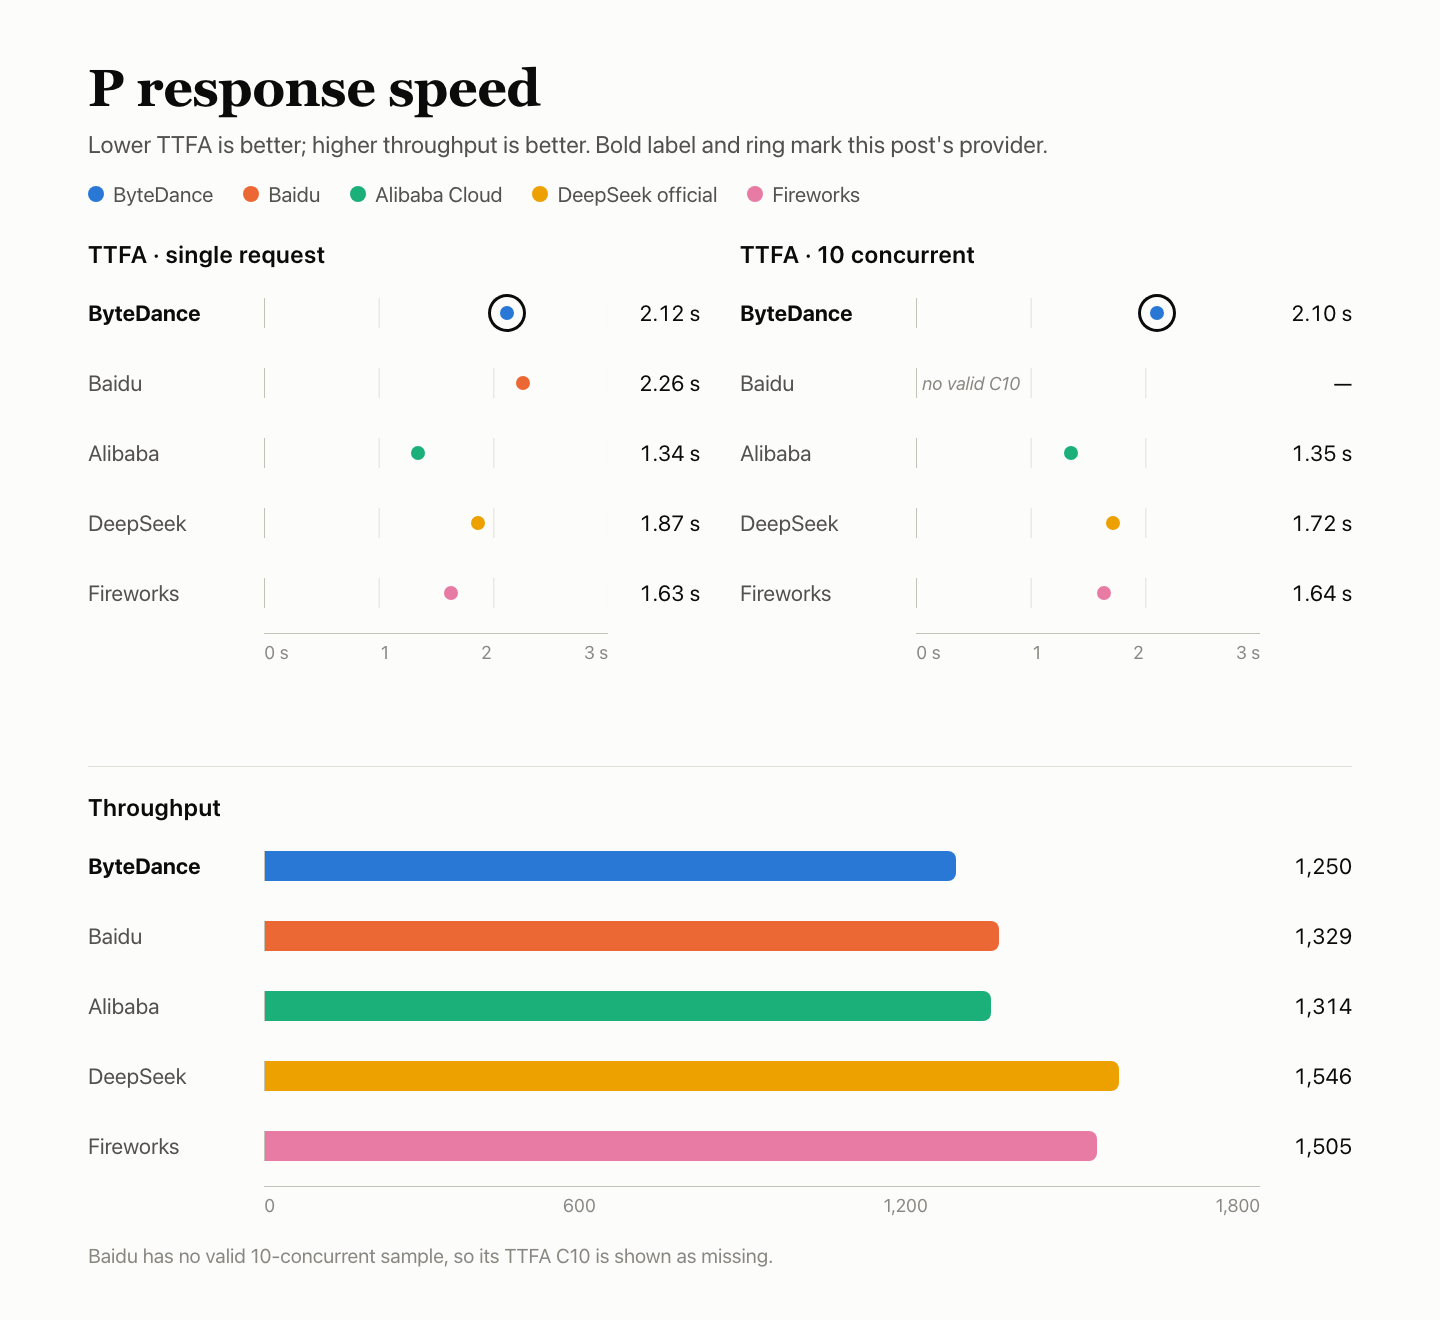
reasoning_effort=nonedoes not turn thinking off. A 10k-token input was reported as 10,026 tokens (native count 10,000); an 8-token input was reported as 34. - P 84.37. First body token: 2.12 s median at single concurrency and 2.10 s at 10-way; TPOT 3.43 ms/token; all 180 speed requests were valid.
- K 93.83. 8k hot requests hit 9/9; 32k hit 8 times, and one request did not finish by the 300 s deadline.
- R 100. All 300 dedicated requests succeeded on the first attempt.
Test setup
| Item | Detail |
|---|---|
| Model | DeepSeek V4.1 Flash 1017 |
| Requested model ID | doubao-deepseek-v4.1-flash-1017 |
| Returned model name | deepseek-v4-1-flash-261017 |
| Access route | Via AIHubMix with a provider-specific model ID, not a direct connection to the provider account |
| Parameters | Non-thinking mode, temperature 1.0, max_tokens 16,384, timeout 300 s, no automatic retry |
| Thinking off | Answer-quality, speed, cache and stability requests used native thinking.type=disabled (for this provider, reasoning_effort=none did not turn thinking off); function cases kept reasoning_effort=none to check whether the parameter takes effect |
| Time | 2026-11-03 18:07 – 11-04 16:33 UTC+8; five providers shared one Mac mini, one network and one account |
| Samples | Answer quality 4,250 question-instances (BFCL 500 × 3, HLE 250 × 10, AA-LCR 25 × 10); function 60 cases × 3 windows; speed 90 single-concurrency and 90 10-way; stability 300; cache 30 (three groups each at 8k and 32k prefixes) |
Requests used the AIHubMix quick start route with a provider-specific ID, and the parameters follow DeepSeek’s API documentation; other provider IDs are listed on the models page.
Q — answer quality: 42.05
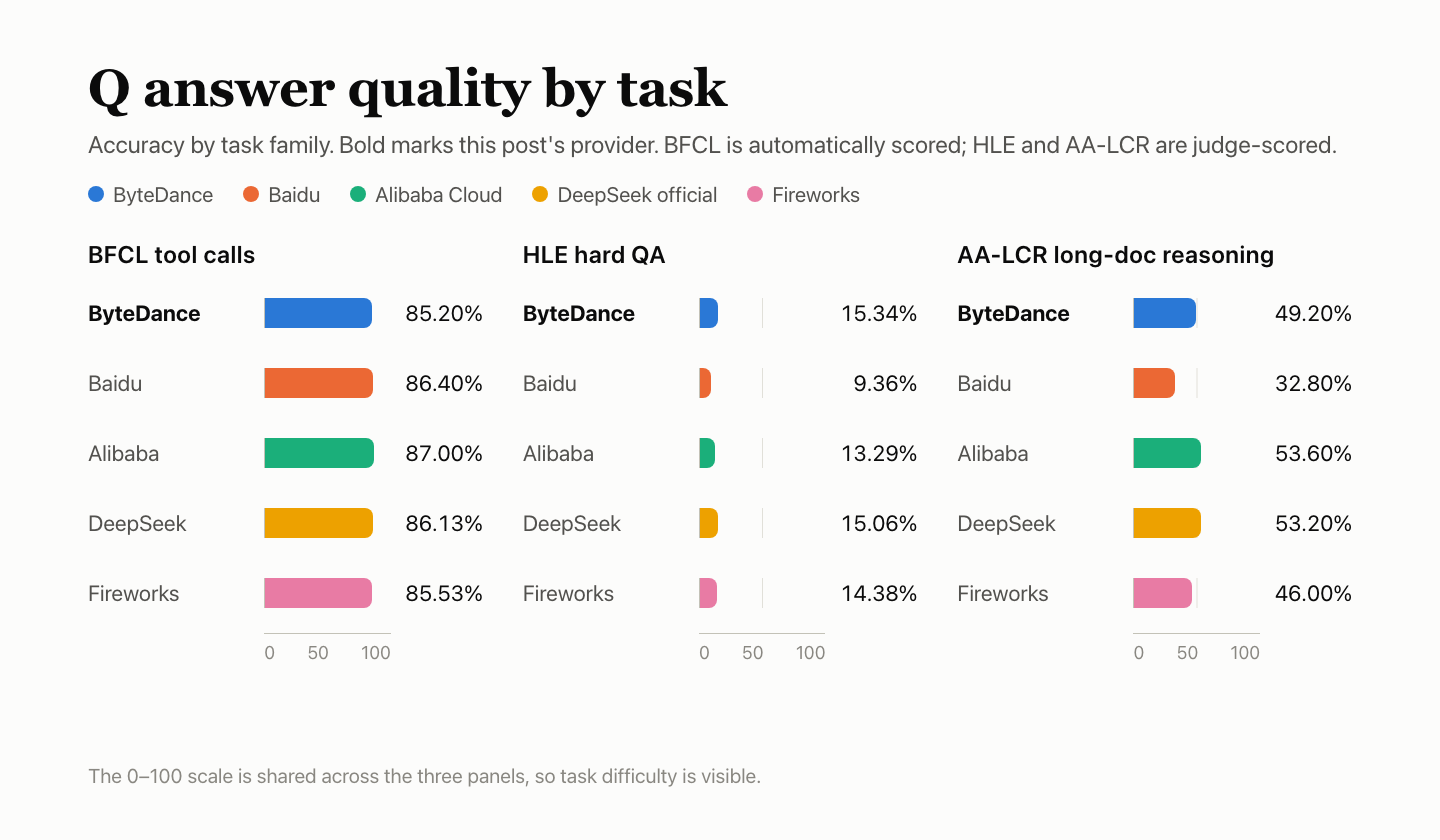
Answer quality draws on three suites: 500 BFCL questions with 3 rounds each, 250 HLE questions with 10 rounds each, and 25 AA-LCR questions with 10 rounds each. BFCL is scored by automatic rules; HLE and AA-LCR are judged by the model deepseek-flash. All five providers received the same questions, and the three suites are pooled into one accuracy. Ten answers were removed because the question could not be scored, leaving 4,240 scored question-instances.
| Suite | Questions | Correct | Accuracy | Failures |
|---|---|---|---|---|
| BFCL tool calls | 500 × 3 | 1,278/1,500 | 85.20% | 0 |
| HLE hard QA | 250 × 10 | 382/2,490 | 15.34% | 7 |
| AA-LCR long-doc reasoning | 25 × 10 | 123/250 | 49.20% | 28 |
| Combined · 95% interval 39.70%–44.33% | — | 1,783/4,240 | 42.05% | 35 |
Service failures — request failures or truncated output — stay in the denominator and count as wrong. HLE output hit the max_tokens ceiling 7 times; AA-LCR had 28 request failures, all in window 1. BFCL is automatically scored; HLE and AA-LCR are judge-scored.
Each BFCL question was answered 3 times; the table sums the 3 rounds.
| BFCL category | Passed | Pass rate |
|---|---|---|
| simple_python — one function, correct call and arguments | 329/360 | 91.39% |
| multiple — choose one of several functions | 268/300 | 89.33% |
| parallel — call the same function several times | 271/300 | 90.33% |
| parallel_multiple — call several different functions | 207/240 | 86.25% |
| irrelevance — no function is relevant, should not call | 102/150 | 68.00% |
| ahm_multi_turn — three-stage tool chain | 101/150 | 67.33% |
Compared with the other four
Difference from official in percentage points, with the 95% interval shown as whiskers. An interval that crosses 0 is recorded as not distinguishable. The HLE and AA-LCR judge, deepseek-flash, belongs to the same DeepSeek family as the tested model and was not calibrated, so its judgments may be lenient.
F — function support: 74.98
The function suite looks only at whether interface behaviour matches the protocol, not at whether the model answers well. Sixty cases in six groups ran three times, once per window: 180 checks, judged against the format each provider documents. Checks that were not applicable, invalid or unobserved leave the denominator. ByteDance passed 124 of 174 counted checks and scored 74.98 on the group weights.
The weighted score applies the group weights; it is not passed checks divided by 174.
| Group | Weight | Passed | Excluded | Group score |
|---|---|---|---|---|
| Streaming and message protocol | 20% | 23/27 | 3 | 85.19 |
| Tool interface | 20% | 30/30 | — | 100.00 |
| Output constraints and parameters | 20% | 24/30 | — | 80.00 |
| Context and state | 15% | 14/30 | — | 46.67 |
| Error and recovery | 15% | 21/30 | — | 70.00 |
| Metering and cache protocol | 10% | 12/27 | 3 | 44.44 |
| Total · weighted score | — | 124/174 | 6 | 74.98 |
“Windows failed” is how many of the 3 windows failed the check.
| Failed case | Windows failed | Reason |
|---|---|---|
| Reasoning does not leak into content — streaming and message protocol | 3/3 | With reasoning_effort=none, thinking content was still returned |
| Thinking configuration takes effect — output constraints and parameters | 3/3 | With reasoning_effort=none, thinking content was still returned |
| Sampling diversity — output constraints and parameters | 3/3 | Outputs at temperature 0 and 1 were not different enough; below the pre-registered threshold |
| 10k long input — context and state | 3/3 | Reported input 10,026 tokens; native count should be 10,000 |
| Within context limit — context and state | 3/3 | Reported input 10,026 tokens; native count should be 10,000 |
| 32k long input — context and state | 3/3 | Reported input 10,026 tokens; native count should be 10,000 |
| 100k long input — context and state | 3/3 | Reported input 10,026 tokens; native count should be 10,000 |
| Over context limit — context and state | 3/3 | Upstream connection failure or timeout (1); should return a parameter error, returned 200 (2) |
| 12-turn history — context and state | 1/3 | Upstream connection failure or timeout |
| messages format error — error and recovery | 3/3 | Returned 400 with an empty body; no structured error explanation |
| Orphan tool result — error and recovery | 3/3 | Should return a parameter error, returned 200 |
| stream_options format error — error and recovery | 3/3 | Returned 400 with an empty body; no structured error explanation |
| Thinking token accounting — metering and cache protocol | 3/3 | Reported thinking tokens after thinking was disabled |
| Native input count — metering and cache protocol | 3/3 | Reported 34 tokens; native count should be 8 |
| Tool definitions counted in input — metering and cache protocol | 3/3 | The control request without tools already disagreed with the native input count |
| Input count consistent before and after cache — metering and cache protocol | 3/3 | When the same prefix was repeated, reported input tokens did not match the native count |
| Streaming and non-streaming input consistent — metering and cache protocol | 3/3 | Both reported 34 tokens; native count should be 8 |
| Exact text output — streaming and message protocol | 1/3 | One extra period at the end of the body; not the exact text requested |
These checks leave the denominator; they count as neither a pass nor a failure.
| Status | Case | Count | Reason |
|---|---|---|---|
| Unobserved | Streaming stop sequences | 3 | After the previous step, this request was not sent; cannot judge |
| Not applicable | Explicit cache_control | 3 | Registered in advance as unsupported by this interface |
The messages format error and stream_options format error cases failed on all five providers: both returned 400 with an empty body, so clients get no structured error explanation. A failure shared by all five is more likely at the AIHubMix gateway layer and needs a separate investigation. Thinking token accounting also failed on all five, but for different reasons: ByteDance and Fireworks reported thinking tokens after thinking was disabled; the other three did not return a thinking-token count.
Compared with the other four
P — response speed: 84.37
Each request carried about 10,000 input tokens and asked for about 1,100 output tokens of body text. In each of three windows, 30 requests ran at single concurrency and 30 at 10-way concurrency: 180 requests in all.
| Metric | Result |
|---|---|
| First body-token wait (TTFA) | 2.12 s median at single concurrency; 2.10 s median at 10-way |
| Generation speed (TPOT) | 3.43 ms/token at single concurrency; 3.41 ms/token at 10-way |
| Effective throughput | 1,250.0 token/s at 10-way |
| Valid requests | 90/90 single; 90/90 at 10-way |
| Component scores | TTFA 48.59, TPOT 100.00, throughput 100.00; TTFA and TPOT take the lower of the two tiers; weights 35% / 35% / 30%; response score 82.00 |
| P score | Response score 82.00 at 80%, cache K 93.83 at 20%; total 84.37 |
TPOT is estimated from streamed chunks, not measured per token on the hardware. Throughput is valid output tokens at 10-way concurrency divided by batch wall-clock time.
Compared with the other four
All five shared one machine, network and account. The three windows were scheduled provider by provider, so collection periods do not fully overlap; small differences should not be over-read.
K — cache: 93.83
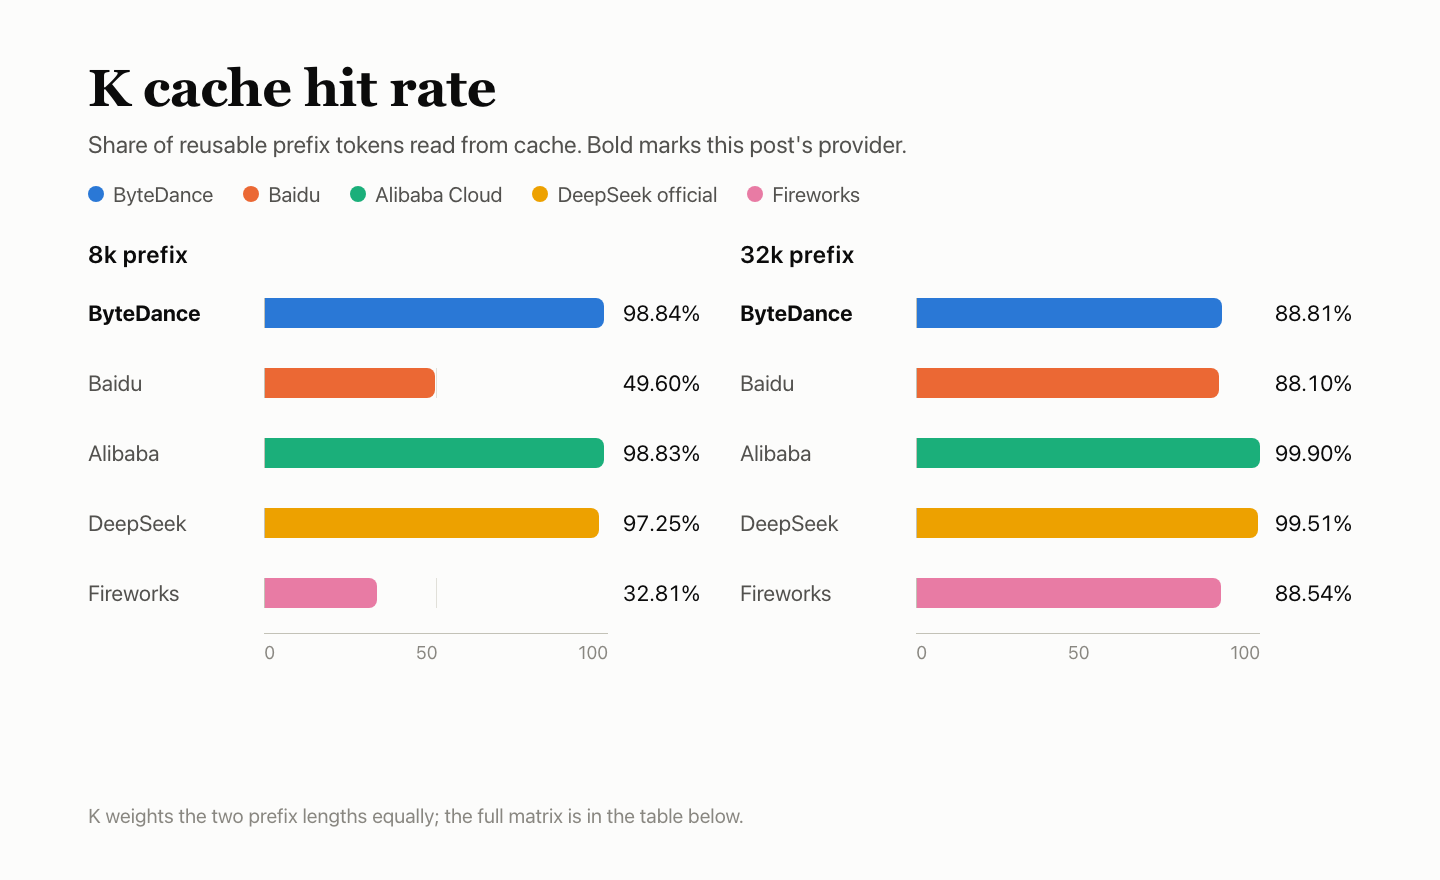
Each group sends five requests. The first carries a fixed prefix of about 8k or 32k tokens and seeds the cache. Requests 2–4 keep the prefix and change only the final question, at 5 s, 30 s and 120 s. The fifth uses a new prefix as a cold control. Three windows and two lengths, five requests per group, give 30 requests. K is cache-read tokens on hot requests divided by the tokens that should be reusable under the rules, with the two lengths weighted equally; K is 20% of P.
| Prefix | Window | Seed | +5 s | +30 s | +120 s | Cold control |
|---|---|---|---|---|---|---|
| 8k | Window 1 | 0 | 7,936 | 7,936 | 7,936 | 0 |
| 8k | Window 2 | 0 | 7,936 | 7,936 | 7,936 | 0 |
| 8k | Window 3 | 0 | 7,936 | 7,936 | 7,936 | 0 |
| 32k | Window 1 | 0 | 32,000 | 32,000 | 32,000 | 0 |
| 32k | Window 2 | 0 | 32,000 | 32,000 | failed | 0 |
| 32k | Window 3 | 0 | 32,000 | 32,000 | 32,000 | 0 |
Values are cache-read tokens reported by the server.
All nine 8k hot requests hit, each reading 7,936 tokens. Eight of nine 32k hot requests hit, each reading 32,000 tokens; one request failed. K is 93.83 with the two lengths weighted equally. Cold requests read no cache, so hot and cold separate cleanly. The failed request is the 32k group’s fourth request in window 2, which reached the 300 s deadline without completing.
Compared with the other four
R — service stability: 100
The 300 requests fall into four types — short text, long input, tool calls and multi-turn history — and ran at single concurrency in three windows. A request counts as a success only if the first attempt returned a valid, complete response; answer correctness is not checked and there is no retry. Failures in the answer-quality and speed sections are counted in Q and P, not again in R.
| Request type | First-attempt success |
|---|---|
| Short text | 120/120 |
| 10k long input | 90/90 |
| Tool calls | 60/60 |
| Multi-turn history | 30/30 |
| Total · 95% interval 98.78%–100% | 300/300 |
All 300 requests returned a valid, complete response on the first attempt. R = 100 describes these 300 dedicated requests only; it does not mean the whole chain had no failures. The lower bound of the 95% interval is 98.78%: 300 successes can only say the failure rate is likely below 1.22%.
Compared with the other four
R covers only these 300 dedicated requests; failures in the answer-quality and speed sections are recorded in Q and P and are not counted again in R.
| Provider | First-attempt success | 95% interval |
|---|---|---|
| ByteDance | 300/300 | 98.78%–100% |
| Baidu | 300/300 | 98.78%–100% |
| Alibaba Cloud | 300/300 | 98.78%–100% |
| DeepSeek official | 300/300 | 98.78%–100% |
| Fireworks | 300/300 | 98.78%–100% |
FAQ
Did reasoning_effort=none actually fail to turn thinking off?
Yes. In all three windows, requests with reasoning_effort=none still returned thinking content, so the check failed 3/3. Answer-quality, speed, cache and stability requests used the native thinking.type=disabled switch instead. The function suite kept reasoning_effort=none on purpose, to test whether the parameter took effect.
BFCL accuracy is 85.20%. Why is Q 42.05?
Q pools three suites of very different difficulty. BFCL contributed 1,278 correct out of 1,500, HLE 382 out of 2,490, and AA-LCR 123 out of 250. Combined, 1,783 of 4,240 scored question-instances were correct: 42.05%. HLE’s 15.34% pulls the pooled figure down.
Are the 35 Q service failures included in the score?
Yes. Request failures and truncated output stay in the denominator and count as wrong. Seven HLE answers were cut off at max_tokens; 28 AA-LCR requests failed, all in window 1.
Why does input token accounting matter?
Because metering should match the model’s native count. A 10k-token input was reported as 10,026 tokens (native 10,000), and an 8-token input was reported as 34. The control request without tools already disagreed, and streaming and non-streaming both reported 34. Five metering checks failed 3/3.
Was the 32k cache result a miss or a failure?
A failure. Eight of nine 32k hot requests hit and read 32,000 tokens. The one miss is the fourth request in window 2, which reached the 300 s deadline without completing. The 8k group hit 9/9 at 7,936 tokens.
Is ByteDance’s answer quality distinguishable from the official channel?
No. The combined accuracy is 0.40 points lower than the official channel, with a 95% interval of −1.46 to +0.66. The interval includes 0, so the two are not distinguishable. This describes this batch only and is not a ranking.
Keep reading: the DeepSeek V4.1 Flash series
- The Q baseline in this post is the official channel; its own run, including the 15 invalid single-concurrency probes, is covered in DeepSeek V4.1 Flash on the official channel: 94.00 F, 15 invalid probes.
- Baidu is the one provider whose Q interval sits below the official channel; the channel failures behind that result are in DeepSeek V4.1 Flash on Baidu: no available channel hits Q and P.
- Alibaba Cloud’s cache figures sit next to the 93.83 reported here: DeepSeek V4.1 Flash on Alibaba Cloud: 1.34s first token, 99.37 cache.
- Fireworks shares the thinking and token-accounting failures seen here, and adds empty stop replies: DeepSeek V4.1 Flash on Fireworks: empty stop replies, 3/9 cache hits.


