

In the 2026-11-03/04 APB Full run, Pareto's four scores are Q 44.58, F 93.42, P 57.69 and R 100, with an overall of 68.72. The 8k hot requests hit 2 of 9 and 32k hit 3 of 9.
On 2026-11-03/04, DeepSeek V4.1 Flash 1017 was tested on six providers through AIHubMix with the APB Full suite, using the same questions, parameters and request scripts for each. This APB Profile covers Pareto only: what each section measured and how it came out.
The numbers below are scores, not a ranking or a provider recommendation. The four scores, Q, F, P and R, come first; the overall is a summary index, not a certification, and it has no confidence interval. The scoring rules are defined in AIHubMix Provider Benchmark Standard v2.0.
Scores across six providers
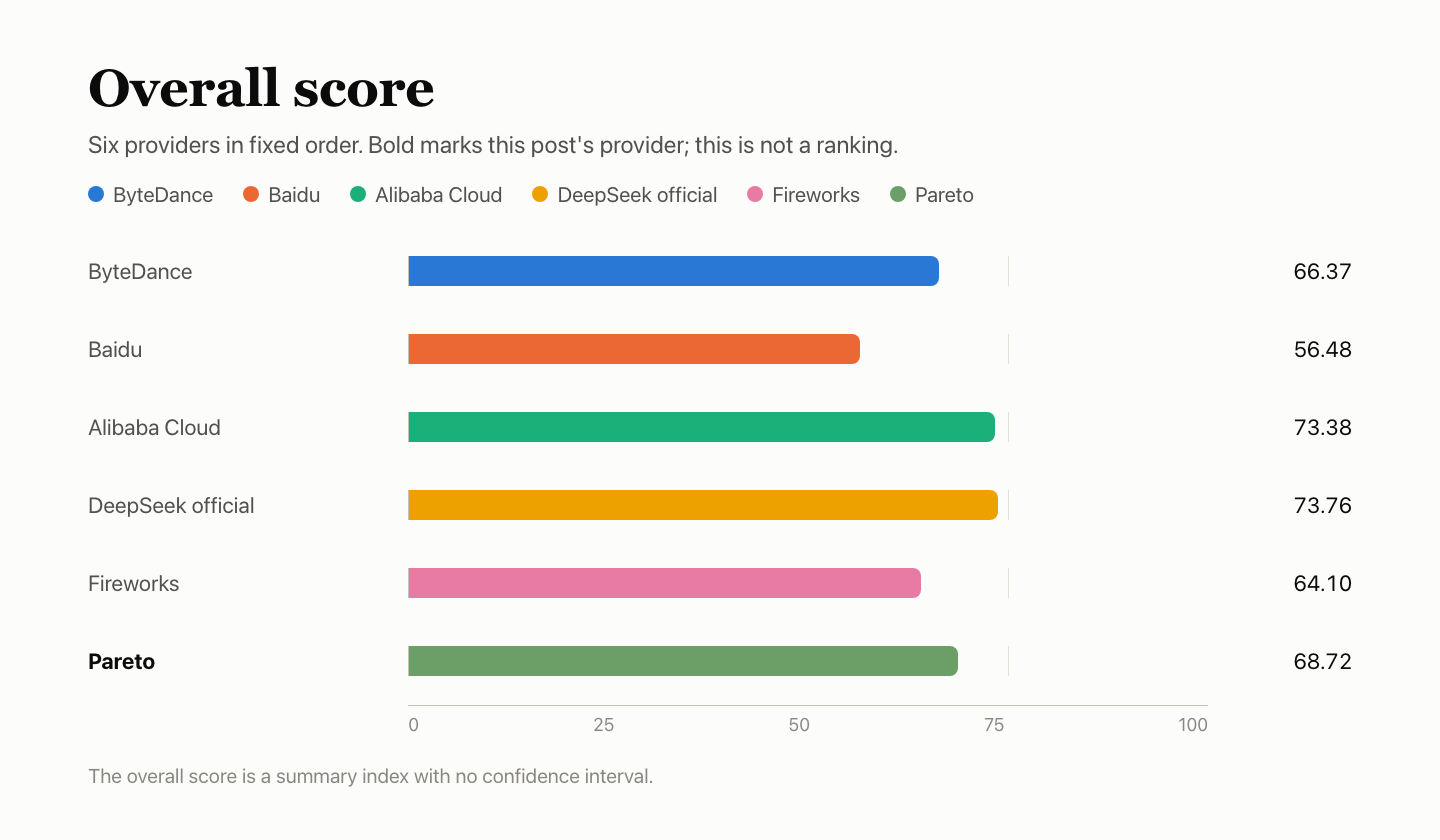
| Provider | Q quality | F function | P speed | K cache | R stability | Overall |
|---|---|---|---|---|---|---|
| ByteDance | 42.05 | 74.98 | 84.37 | 93.83 | 100 | 66.37 |
| Baidu | 38.00 | 88.39 | 37.77 | 68.85 | 100 | 56.48 |
| Alibaba Cloud | 41.75 | 89.78 | 88.58 | 99.37 | 100 | 73.38 |
| DeepSeek official channel | 42.45 | 94.00 | 86.14 | 98.38 | 100 | 73.76 |
| Fireworks | 41.42 | 71.78 | 79.51 | 60.68 | 100 | 64.10 |
| Pareto (this post) | 44.58 | 93.42 | 57.69 | 27.58 | 100 | 68.72 |
Providers are listed in a fixed order, not a ranking. K is a sub-score of P, accounting for 20% of it, and is listed separately for reference. The overall score is computed with the composition rules of AIHubMix Provider Benchmark Standard, which also take in the comparison with the official channel and evidence completeness; it is not a direct weighting of the four scores in the table. It is a summary index with no confidence interval. The DeepSeek official channel and Alibaba Cloud differ by only 0.37 overall, which is not a distinguishable difference.
At a glance
- Answer quality: Q 44.58, with BFCL 85.27%, HLE 19.32% and AA-LCR 52.00%. The gap to the official channel is +2.12 percentage points, with a 95% interval of −0.02 to +4.18: not distinguishable.
- Function support: F 93.42, with 29/33 original scored checks passing. Tool calls and tool-result round-trip, parallel and named calls, JSON mode and conversation history have additional successful streaming records; scores retain their original values.
- Response speed: P 57.69. Median first body token 5.85 s at single concurrency and 6.13 s at 10-way, TPOT 4.63 ms; 110 of 180 speed requests were valid.
- Cache: K 27.58. The 8k hot requests hit 2 of 9 and the 32k hot requests 3 of 9; no cold control read the cache.
- Service stability: R 100. All 300 dedicated requests succeeded on the first attempt.
Test setup
| Item | Detail |
|---|---|
| Model | DeepSeek V4.1 Flash 1017 |
| Requested model ID | deepseek/deepseek-v4.1-flash |
| Returned model name | deepseek/deepseek-v4.1-flash |
| Access route | Through AIHubMix with a provider-specific model ID, not a direct connection to the provider's account |
| Parameters | Fixed APB v2 request profile, temperature 1.0, max_tokens 16,384, 300 s timeout, no automatic retry |
| Time | 2026-11-03 18:07 – 11-04 16:33; cache requests 11-05 19:31 – 11-06 10:35; all UTC+8. All six providers shared one Mac mini, one network and one account. |
| Samples | Q 4,250 question-instances; F 180 checks; P 180 requests; R 300; K 30 |
Requests used the AIHubMix quick start route with a provider-specific model ID; the other providers' IDs are listed on the models page. The model's own parameters are described in DeepSeek's API documentation.
Q — answer quality: 44.58
Answer quality draws on three suites: 500 BFCL questions answered 3 times each, 250 HLE questions answered 10 times each, and 25 AA-LCR questions answered 10 times each. BFCL is scored by automatic rules; HLE and AA-LCR are judged right or wrong by the judge model deepseek-flash. All six providers received the same questions, and the three suites are pooled into one accuracy. Ten answers were removed because the question could not be scored, leaving 4,240 scored question-instances.
| Suite | Questions × rounds | Correct | Accuracy | Service failures |
|---|---|---|---|---|
| BFCL tool calls, auto-scored | 500 × 3 | 1,279/1,500 | 85.27% | 0 |
| HLE hard QA, judge-scored | 250 × 10 | 481/2,490 | 19.32% | 0 |
| AA-LCR long-doc reasoning, judge-scored | 25 × 10 | 130/250 | 52.00% | 0 |
| Total · 95% interval 41.57%–47.49% | — | 1,890/4,240 | 44.58% | 0 |
Every question-instance received a complete answer; there were no service failures.
| BFCL category | Passed | Pass rate |
|---|---|---|
| simple_python: one function, right call and arguments | 333/360 | 92.50% |
| multiple: pick the right one of several functions | 269/300 | 89.67% |
| parallel: one function called several times at once | 265/300 | 88.33% |
| parallel_multiple: several functions at once | 203/240 | 84.58% |
| irrelevance: no relevant function, so no call | 109/150 | 72.67% |
| ahm_multi_turn: three-stage tool chain | 100/150 | 66.67% |
Each BFCL question was answered 3 times; the table sums the 3 rounds.
Compared with the other five
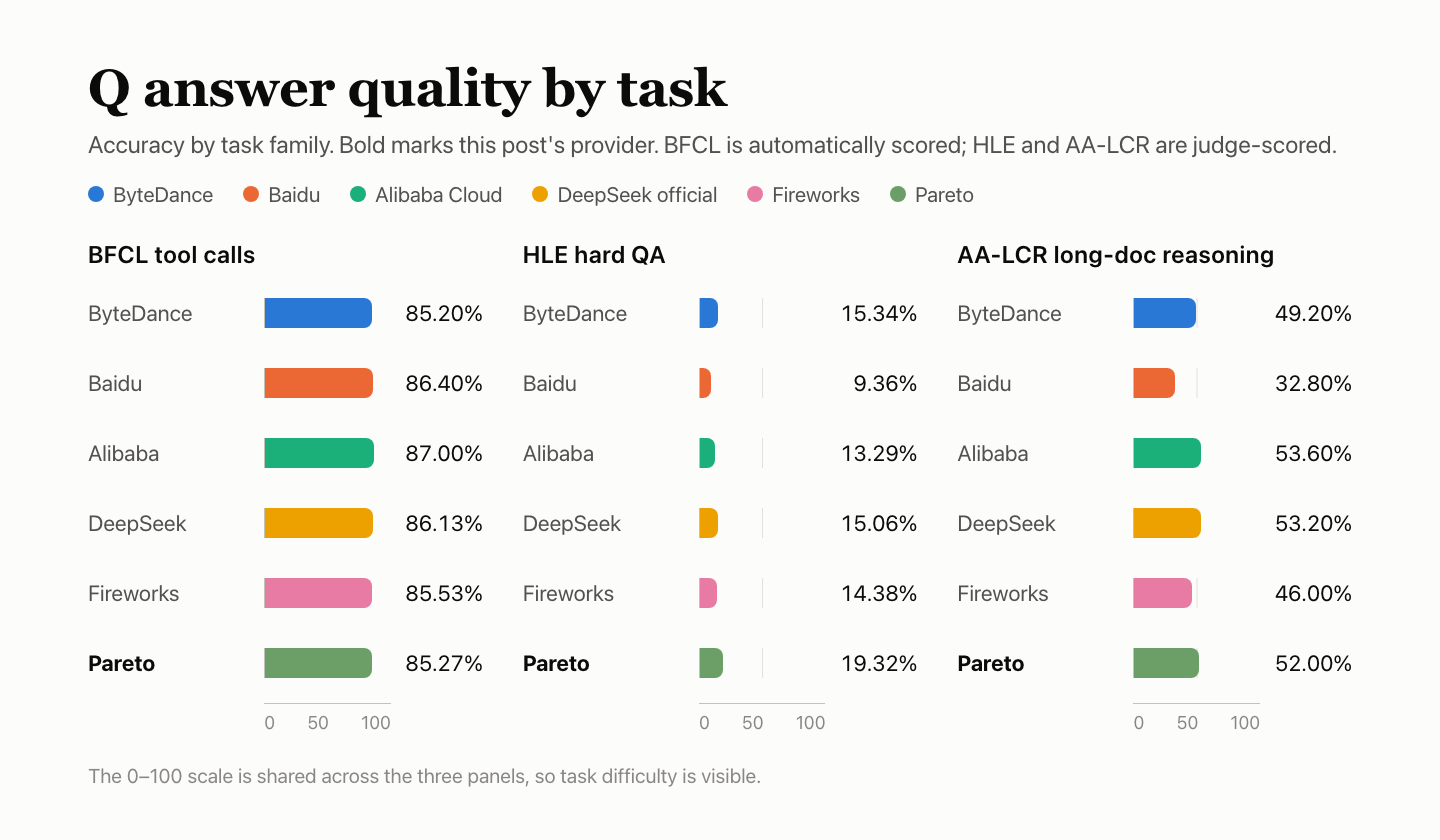
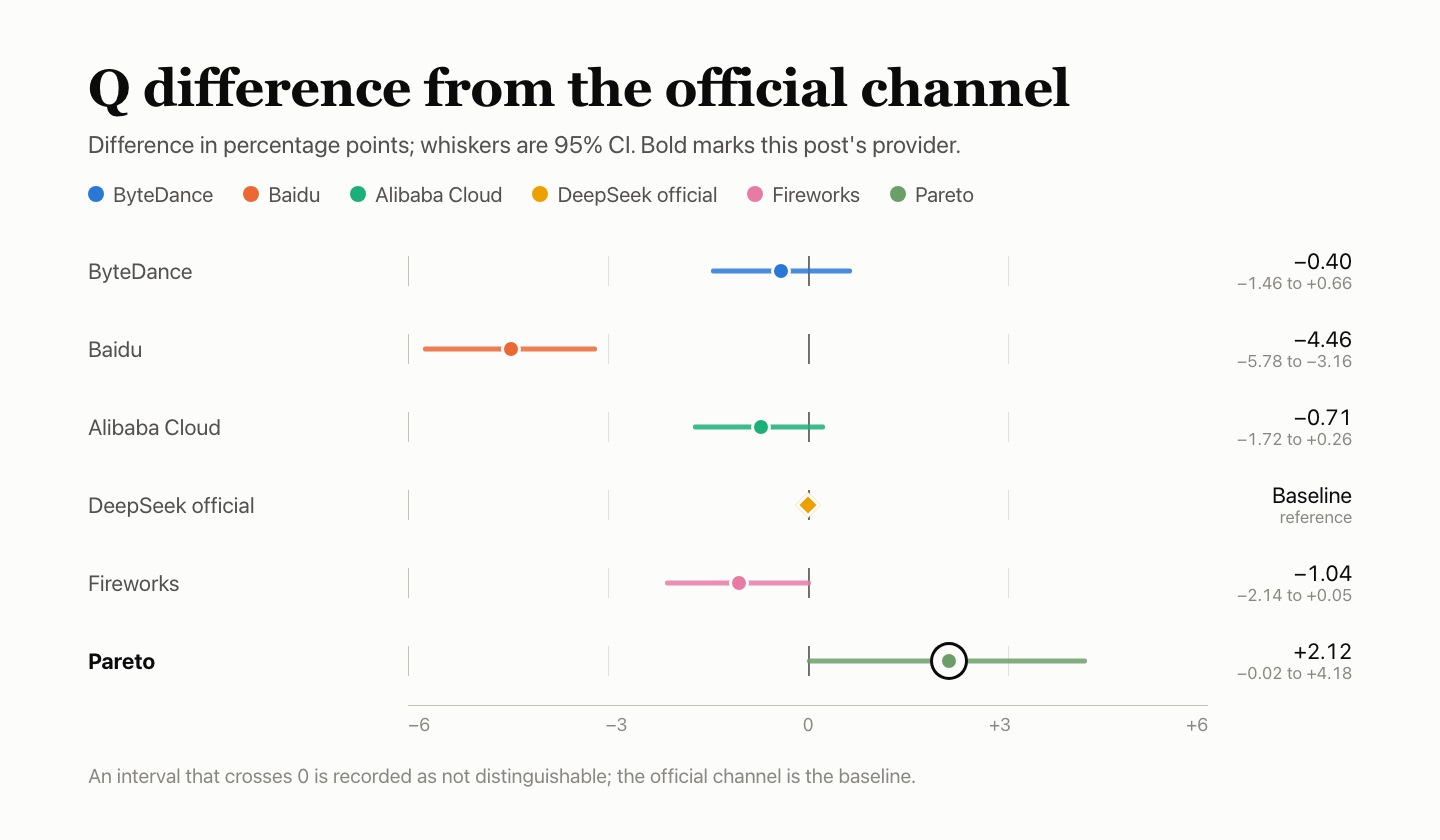
| Provider | BFCL | HLE | AA-LCR | Combined | Vs official |
|---|---|---|---|---|---|
| ByteDance | 85.20% | 15.34% | 49.20% | 42.05% | −0.40 (−1.46 to +0.66), not distinguishable |
| Baidu | 86.40% | 9.36% | 32.80% | 38.00% | −4.46 (−5.78 to −3.16), below official |
| Alibaba Cloud | 87.00% | 13.29% | 53.60% | 41.75% | −0.71 (−1.72 to +0.26), not distinguishable |
| DeepSeek official channel | 86.13% | 15.06% | 53.20% | 42.45% | Baseline |
| Fireworks | 85.53% | 14.38% | 46.00% | 41.42% | −1.04 (−2.14 to +0.05), not distinguishable |
| Pareto (this post) | 85.27% | 19.32% | 52.00% | 44.58% | +2.12 (−0.02 to +4.18), not distinguishable |
Vs official: the accuracy gap in percentage points, with the 95% interval in brackets; an interval that crosses 0 is recorded as not distinguishable. The HLE and AA-LCR judge, deepseek-flash, belongs to the same DeepSeek family as the tested model and was not calibrated, so its judgments may be lenient.
F — function support: 93.42
The function cases check whether interface behaviour matches the protocol. F 93.42 comes from the 33 counted checks (29 passed), after renormalising the observed group weights; the other 147 planned check slots in the original suite were excluded from scoring.
| Case group | Weight | Passed / streaming observations | Excluded | Group score |
|---|---|---|---|---|
| Streaming and message protocol | 20% | 23/27 | 3 | 85.19 |
| Tool interface Tool calls, tool-result round-trip, parallel and named calls | 20% | Streaming passes observed* | 30 | — |
| Output constraints and parameters JSON mode and thinking disabled | 20% | Streaming passes observed* | 30 | — |
| Context and state Conversation history and system instructions | 15% | Streaming passes observed* | 30 | — |
| Errors and recovery | 15% | 3/3 | 27 | 100.00 |
| Metering and cache protocol | 10% | 3/3 | 27 | 100.00 |
| Total · weighted score | 29/33 | 147 | 93.42 | |
- The listed features have successful streaming records; this does not award full marks to the whole group. No checks are added to scoring. F 93.42 and the overall of 68.72 retain their original values.
| Failed case | Windows | Reason |
|---|---|---|
| Streaming stop sequence Streaming and message protocol | 3/3 | Empty body with a stop sequence; the same input without stop worked |
| Exact text output Streaming and message protocol | 1/3 | An extra final period broke the exact-text match |
“Windows” is how many of the 3 windows failed the check.
The malformed-messages and malformed-stream-options cases returned 400 with an empty response body on several providers. Reasoning-token metering behaved differently across providers.
Compared with the other five
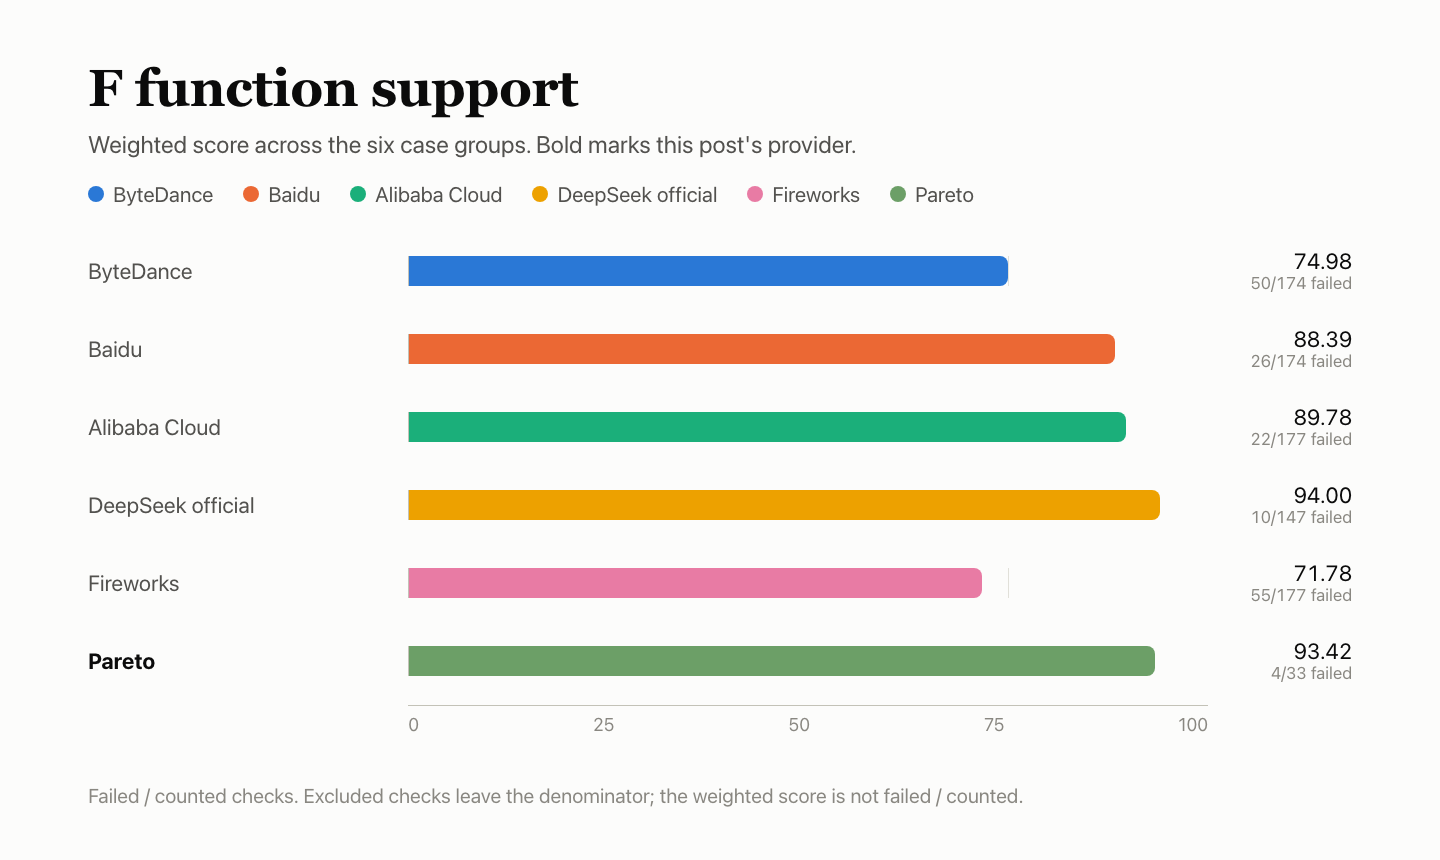
| Provider | Passed | Failed | Excluded | Weighted score |
|---|---|---|---|---|
| ByteDance | 124 | 50 | 6 | 74.98 |
| Baidu | 148 | 26 | 6 | 88.39 |
| Alibaba Cloud | 155 | 22 | 3 | 89.78 |
| DeepSeek official channel | 137 | 10 | 33 | 94.00 |
| Fireworks | 122 | 55 | 3 | 71.78 |
| Pareto (this post) | 29 | 4 | 147 | 93.42 |
P — response speed: 57.69
Each request carried about 10,000 input tokens and asked for about 1,100 output tokens of body text. In each of three windows, 30 requests ran at single concurrency and 30 at 10-way concurrency: 180 requests in all.
| Item | Detail |
|---|---|
| First body token (TTFA) | Median 5.85 s single (valid-only 3.08 s), 6.13 s at 10-way (valid-only 4.92 s) |
| Generation speed (TPOT) | 4.42 ms/token single, 4.63 ms/token at 10-way |
| Effective throughput | 519.4 token/s at 10-way |
| Valid requests | 53/90 single (windows 1–3: 15/30, 18/30, 20/30), 57/90 at 10-way (23/30, 16/30, 18/30); invalid: 70 returned 200 with None |
| Sub-scores | TTFA 24.59, TPOT 100.00, throughput 72.05; TTFA and TPOT take the lower tier, weighted 35% / 35% / 30%: response score 65.22 |
| P score | Response score 65.22 × 80% + cache K 27.58 × 20% = 57.69 |
Invalid requests are scored as infinite, so the medians in the table can be higher than valid-only medians. TPOT is estimated from streamed chunks, not measured per token on the hardware. Throughput is valid output tokens at 10-way concurrency divided by batch wall-clock time.
Compared with the other five
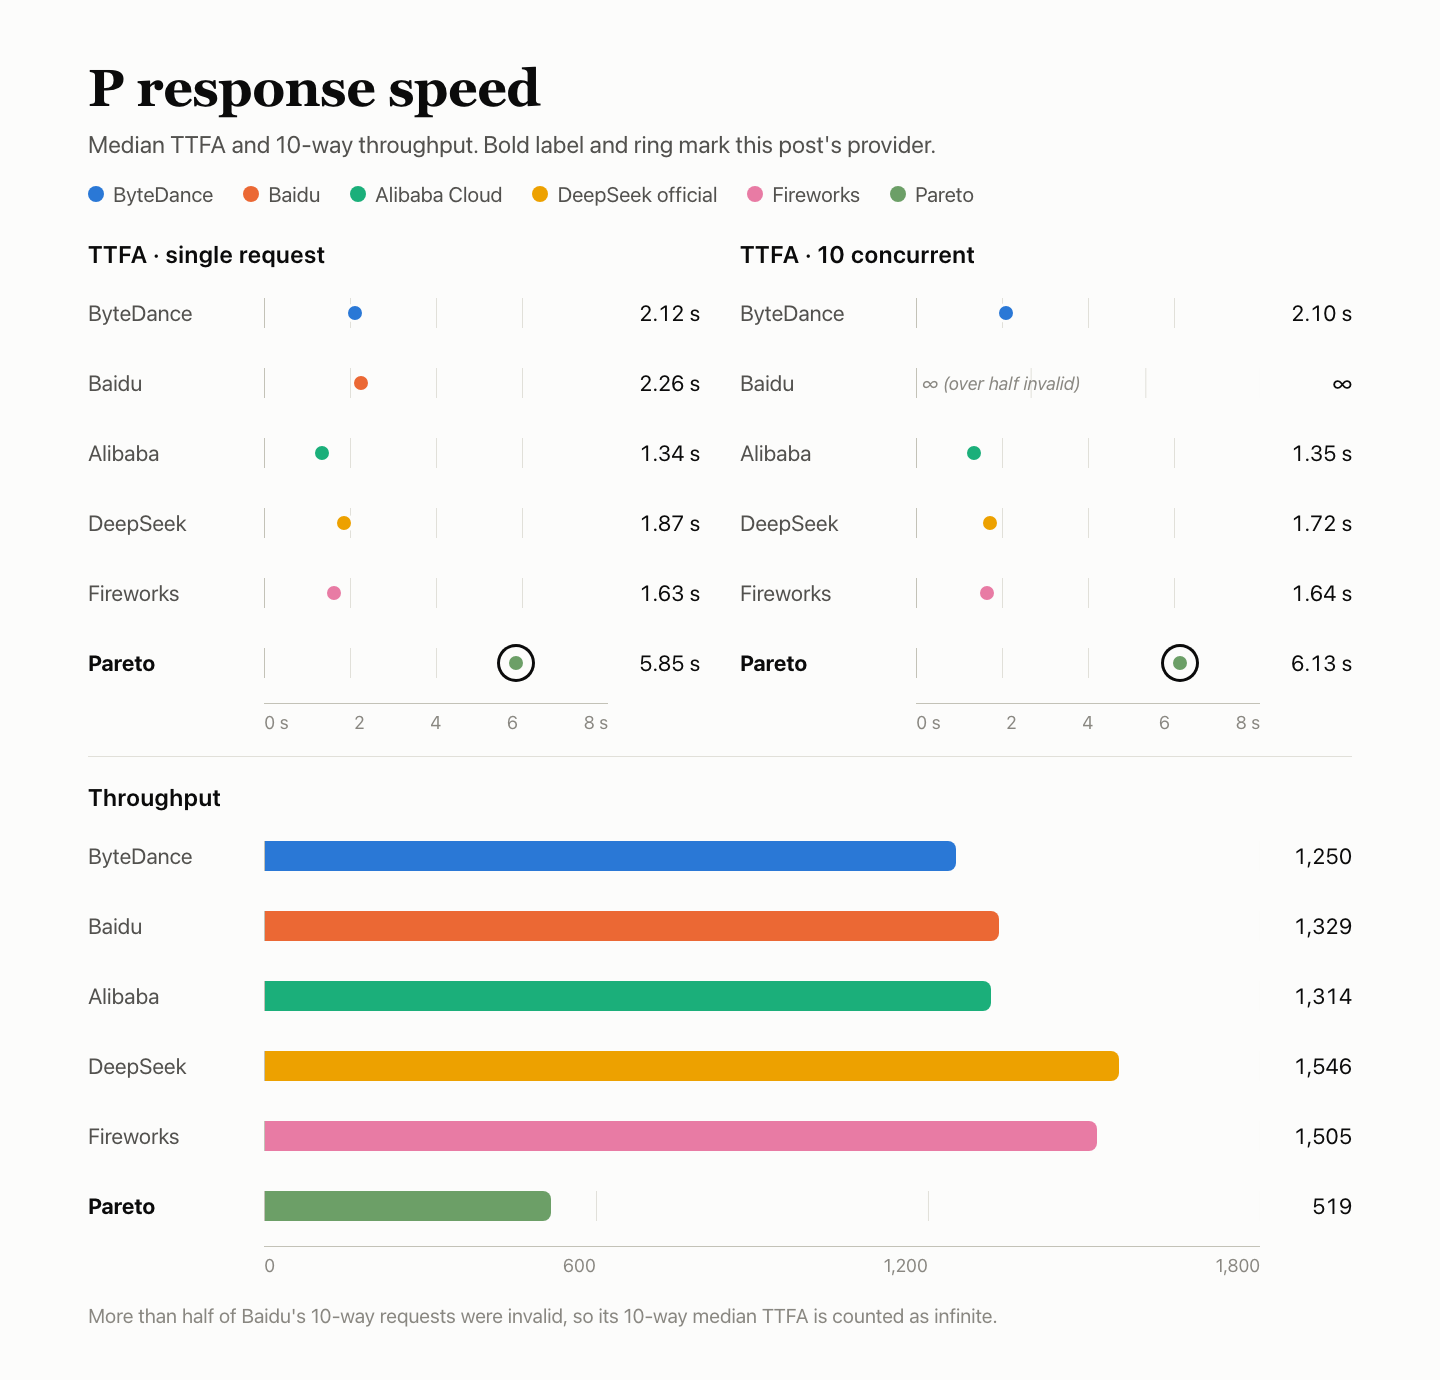
| Provider | Valid requests | TTFA single | TTFA 10-way | TPOT (slower) | Throughput tok/s | Response |
|---|---|---|---|---|---|---|
| ByteDance | 180/180 | 2.12 s | 2.10 s | 3.43 ms | 1,250 | 82.00 |
| Baidu | 118/180 | 2.26 s | ∞ | 50.00 ms | 1,329 | 30.00 |
| Alibaba Cloud | 180/180 | 1.34 s | 1.35 s | 4.69 ms | 1,314 | 85.88 |
| DeepSeek official channel | 165/180 | 1.87 s | 1.72 s | 2.84 ms | 1,546 | 83.08 |
| Fireworks | 179/180 | 1.63 s | 1.64 s | 3.29 ms | 1,505 | 84.22 |
| Pareto (this post) | 110/180 | 5.85 s | 6.13 s | 4.63 ms | 519 | 65.22 |
All six shared one machine, network and account. The three windows were scheduled provider by provider, so collection periods do not fully overlap; small differences should not be over-read. ∞ means more than half the requests were invalid, so the median counts as infinite.
K — cache: 27.58
Each group sends five requests. The first carries a fixed prefix of about 8k or 32k tokens and seeds the cache. Requests 2–4 keep the prefix and change only the final question, at gaps of 5 s, 30 s and 120 s. The fifth uses a new prefix as a cold control. Three windows × two lengths make 30 requests. K is the cache tokens read by hot requests divided by the tokens that should be reusable under the rules, with the two lengths weighted equally; K is 20% of P.
| Window | 1 · seed | 2 · +5 s | 3 · +30 s | 4 · +120 s | 5 · cold |
|---|---|---|---|---|---|
| 8k prefix · hot hits 2/9 · read 15,872 of 72,504 reusable · 21.89 | — | — | — | — | — |
| Window 1 | 0 | 0 | 7,936 | 0 | 0 |
| Window 2 | 0 | 0 | 0 | 0 | 0 |
| Window 3 | 0 | 0 | 7,936 | 0 | 0 |
| 32k prefix · hot hits 3/9 · read 96,000 of 288,513 reusable · 33.27 | — | — | — | — | — |
| Window 1 | 0 | 0 | 32,000 | 0 | 0 |
| Window 2 | 0 | 0 | 0 | 0 | 0 |
| Window 3 | 0 | 0 | 0 | 32,000 | 0 |
| K (8k and 32k weighted equally) | — | — | — | — | 27.58 |
Values are cache-read tokens reported by the server; “Not returned” means the field was absent from the response.
The 8k hot requests hit 2 of 9, reading 7,936 tokens on each hit; the 32k hot requests hit 3 of 9, reading 32,000 tokens on each hit. Cold requests read no cache, so hot and cold separate cleanly.
Compared with the other five
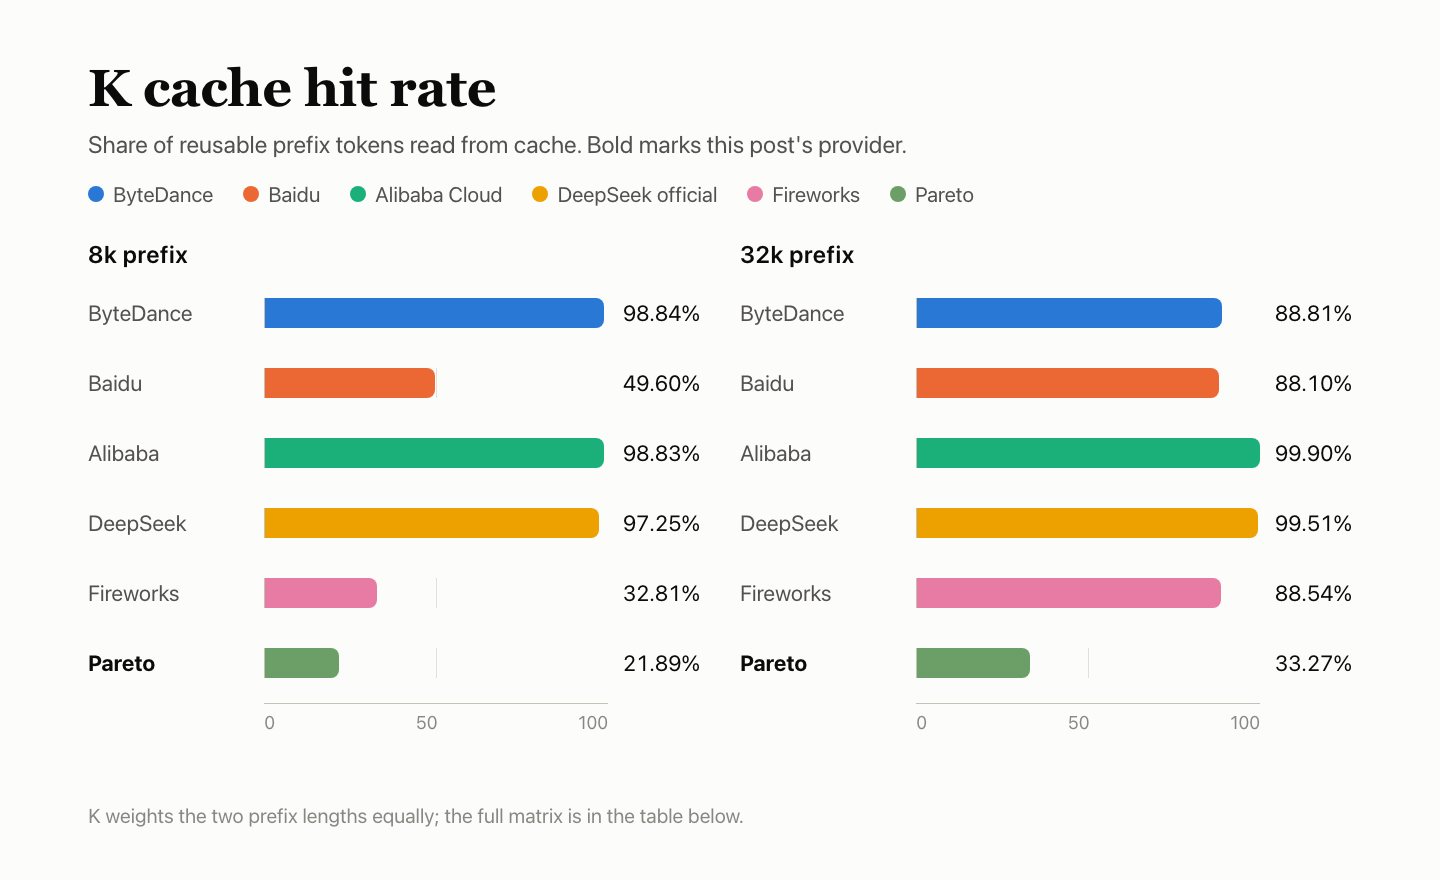
| Provider | 8k hits | 8k | 32k hits | 32k | K |
|---|---|---|---|---|---|
| ByteDance | 9/9 | 98.84 | 8/9 | 88.81 | 93.83 |
| Baidu | 5/9 | 49.60 | 8/9 | 88.10 | 68.85 |
| Alibaba Cloud | 9/9 | 98.83 | 9/9 | 99.90 | 99.37 |
| DeepSeek official channel | 9/9 | 97.25 | 9/9 | 99.51 | 98.38 |
| Fireworks | 3/9 | 32.81 | 8/9 | 88.54 | 60.68 |
| Pareto (this post) | 2/9 | 21.89 | 3/9 | 33.27 | 27.58 |
R — service stability: 100
The 300 requests fall into four types: short text, long input, tool calls and multi-turn history. They ran at single concurrency across three windows. Only whether the first attempt returned a valid, complete response is checked; answers are not graded and nothing is retried. Failures in the answer-quality and speed sections are counted in Q and P, not again in R.
| Request type | First-attempt success |
|---|---|
| Short text | 120/120 |
| 10k long input | 90/90 |
| Tool calls | 60/60 |
| Multi-turn history | 30/30 |
| Total · 95% interval 98.78%–100% | 300/300 |
All 300 requests returned a valid, complete response on the first attempt. R = 100 describes these 300 dedicated requests only; it does not mean the whole chain had no failures. The lower bound of the 95% interval is 98.78%: 300 successes out of 300 can only say the failure rate is likely below 1.22%.
Compared with the other five
| Provider | First-attempt success | 95% interval |
|---|---|---|
| ByteDance | 300/300 | 98.78%–100% |
| Baidu | 300/300 | 98.78%–100% |
| Alibaba Cloud | 300/300 | 98.78%–100% |
| DeepSeek official channel | 300/300 | 98.78%–100% |
| Fireworks | 300/300 | 98.78%–100% |
| Pareto (this post) | 300/300 | 98.78%–100% |
R covers only these 300 dedicated requests; failures in the answer-quality and speed sections are recorded in Q and P and are not counted again in R.
FAQ
Why is F 93.42 when only 33 checks were counted?
The original counted checks passed 29 of 33, producing F 93.42 after renormalising the observed group weights; the other 147 planned check slots were excluded from scoring. The streaming records describe specific working features and add no scored checks. The displayed overall remains 68.72.
Why is P 57.69 when TPOT scored 100.00?
Only 110 of 180 speed requests were valid; 70 returned 200 with None. Invalid requests count as infinite, so the median first body token is 5.85 s single and 6.13 s at 10-way (3.08 s and 4.92 s valid-only). TTFA scored 24.59 and throughput 72.05, for a response score of 65.22; with cache K 27.58 at 20%, P is 57.69.
Why is K only 27.58?
Hot requests hit 2 of 9 at 8k (21.89) and 3 of 9 at 32k (33.27), and the two lengths weigh equally. When a hit happened it read 7,936 or 32,000 tokens, and no cold control read the cache.
Is Pareto's answer quality higher than the official channel's?
Not distinguishably. Combined accuracy is 44.58% against 42.45%, a gap of +2.12 points, but the 95% interval runs from −0.02 to +4.18 and crosses 0. The HLE and AA-LCR judge, deepseek-flash, was not calibrated and may be lenient.
Which F cases failed?
Two. The streaming stop sequence returned an empty body in all three windows, while the same input without stop worked. Exact text output had an extra final period in one of three windows.
Keep reading: the DeepSeek V4.1 Flash series
- Pareto's Q gap of +2.12 is measured against the official channel; the baseline's own run is in DeepSeek official channel DeepSeek V4.1 Flash review: comparison baseline, 15 invalid requests at single concurrency.
- Fireworks also returned empty bodies on stop requests, and hit 3 of 9 at 8k: Fireworks DeepSeek V4.1 Flash review: stop requests return empty body, 8k cache hot requests hit 3 of 9.
- Alibaba Cloud's hot requests hit 18 of 18, against Pareto's 5 of 18: Alibaba Cloud DeepSeek V4.1 Flash review: 1.34s first body token, all 18 hot requests hit cache, answers indistinguishable from official.
- ByteDance's speed requests were all valid, with a 2.12 s first body token: ByteDance DeepSeek V4.1 Flash review: answers indistinguishable from official, input counts don't match.
- Baidu also lost many speed requests, to no_available_channel: Baidu DeepSeek V4.1 Flash review: tool calling on par with official, frequent no-available-channel pulls down answer quality and speed.
Sources
- DeepSeek V4.1 Flash 1017 model page (AIHubMix)
- AIHubMix Provider Benchmark Standard v2.0 (AIHubMix docs)
- Quick start (AIHubMix docs)
- Models (AIHubMix)
- DeepSeek API documentation (DeepSeek)


